Mem++: نگهداری غیرمخرب حافظه بلندمدت برای عاملهای سازمانی
Mem++ اسناد سازمانی را کامل، همراه با تاریخ و نویسنده، نگه میدارد و انتخاب میان نسخههای متعارض را به زمان پاسخگویی واگذار میکند.
فهرست مطالب
این معرفی بر نسخه موجود مقاله در arXiv، با شناسه 2610.02002 و نسخه v1 مورخ ۱ اکتبر ۲۰۲۶، تکیه دارد؛ این یک پیشچاپ است و وضعیت داوری مستقل آن تأیید نشده است. مقاله مسئله حافظه عاملهای زبانی در سازمانها را بررسی میکند؛ جایی که تصمیمها در ایمیل، تیکت، یادداشت جلسه و سندهای متعدد، توسط نویسندگان مختلف و طی ماهها ثبت میشوند. تغییر یک تصمیم معمولاً سند تازهای میسازد، نه ویرایش نسخه قبلی؛ بنابراین پاسخ درست ممکن است به نسخه معتبر در یک تاریخ مشخص وابسته باشد.
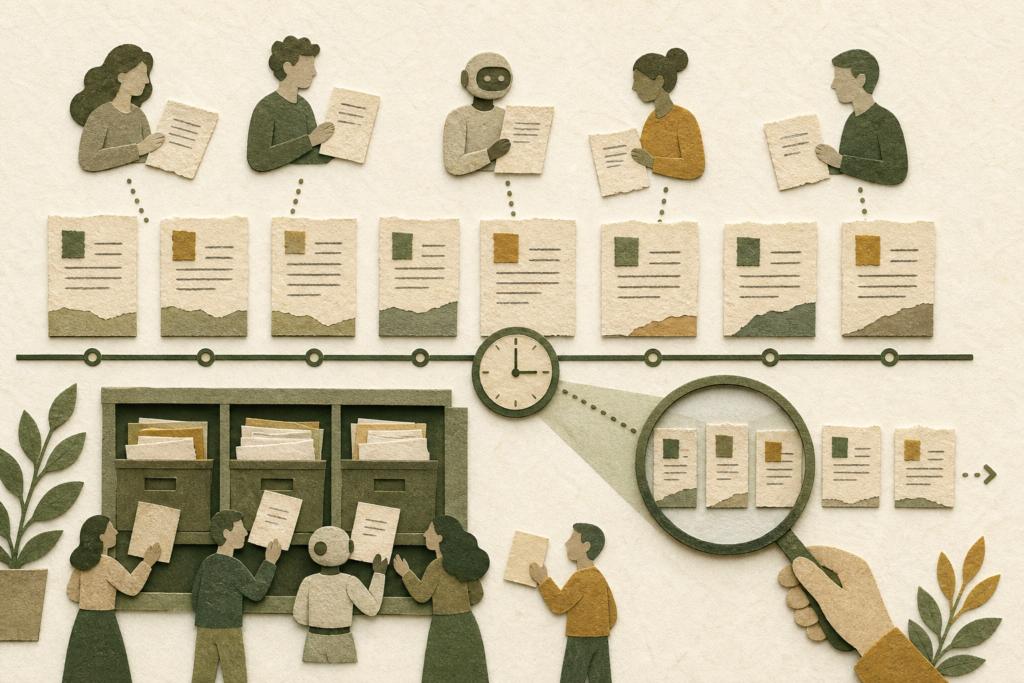
نویسندگان Mem++ را بهعنوان حافظهای «غیرمخرب» معرفی میکنند. این سامانه هر سند را بهطور کامل، همراه متن، نویسنده، تاریخ رخداد، بردار تعبیهسازی و وضعیت آن ذخیره میکند و در مسیر نوشتن از مدل زایشی استفاده نمیکند. رکوردها حذف یا بازنویسی نمیشوند؛ تنها وضعیتشان میتواند نشان دهد که نسخهای بعدی جایگزینشان کرده است. هدف این است که برخلاف استخراج واقعیت یا خلاصهسازی در هنگام ورود، امکان پاسخگویی با اتکا به متن اصلی و همه نسخههای تاریخی حفظ شود.
در زمان خواندن، Mem++ اسناد را از سه مسیر واژگانی، برچسب نویسنده و معنایی بازیابی و رتبهها را با همجوشی رتبه متقابل وزندار ترکیب میکند. اگر پرسش تاریخ مرجع داشته باشد، فقط رکوردهای فعال با تاریخ کمتر یا مساوی آن تاریخ وارد هر سه مسیر میشوند. از ۵۰ رکورد بازیابیشده در آزمایشهای اصلی، سه جایگاه برای تطابقهای باقیمانده با تازهترین تاریخ رخداد کنار گذاشته میشود. متن، تاریخ و در صورت وجود نویسنده، سپس به مدل پاسخدهنده داده میشود.
ارزیابی اصلی روی سطح متوسط OrgMemBench انجام شده است: ۴۴۳ سند تاریخدار در ۱۵۷ رشته طی ۱۸ ماه و ۷۳ پرسش در شش توانایی، از جمله جانشینی، منشأ، دوزمانی و زنجیره توجیه. معیار اصلی، امتیاز داور LLM با gpt-4o-mini است و برای OrgMemBench پاسخها در برابر ۲۴۷ مؤلفه ارزیابی میشوند. دو مجموعه گفتوگومحور LoCoMo و LongMemEval_S نیز بهکار رفتهاند. مقایسه شامل Full Context، RAG، Mem0، Zep و بسته به مجموعه، روشهای دیگری مانند A-Mem، Nemori و gbrain است.
با gpt-4.1-mini، Mem++ در OrgMemBench امتیاز کلی ۵۷٫۶ گرفت؛ این مقدار ۲٫۶ امتیاز بالاتر از RAG و ۱۳٫۱ امتیاز بالاتر از بهترین سامانه حافظهایِ مقایسهشده، A-Mem، بود. با gpt-4o-mini، Mem++ امتیاز ۴۴٫۲ و گونه گرافی Mem_g++ امتیاز ۴۴٫۴ ثبت کردند، در برابر ۴۳٫۴ برای RAG؛ فاصله Mem++ با بهترین سامانه حافظهای دیگر، Zep، ۸٫۰ امتیاز بود. Mem++ در LoCoMo نیز بهترین میانگین امتیاز داور را با هر دو مدل پاسخدهنده گزارش کرد، اما در LongMemEval_S پس از گونه گرافی خود دوم شد. حذف مسیر معنایی در مطالعه حذف مؤلفهها افتهای بزرگی، از جمله ۳۵٫۷ امتیاز در OrgMemBench، ایجاد کرد.
محدودیتها مهماند. ارزیابی سازمانی فقط بر ۷۳ پرسش درباره یک سازمان خیالی تکیه دارد؛ مقاله داده سازمانی واقعی یا متنوعتری گزارش نمیکند. در OrgMemBench فقط ۱۵ پرسش Audit Replay تاریخ مرجع دارند و مدل پاسخدهنده تنها ۴۰٬۰۰۰ نویسه نخست زمینه را میبیند، یعنی حدود ۱۹ ردیف از ۵۰ ردیف بازیابیشده؛ در نتیجه برخی ردیفهای رزرو تازگی و سهتاییهای گرافی ممکن است به مدل نرسند. گونه Mem_g++ نیز سهتاییهای بدون تاریخ دارد و ممکن است در پرسش تاریخدار، اطلاعات پس از تاریخ مرجع را وارد کند. سود گراف میان مدلهای پاسخدهنده نیز پایدار نبوده است.
This overview relies on the available arXiv version of the paper, identifier 2610.02002, v1 dated October 1, 2026; this is a preprint, and its independent peer-review status is not confirmed. The paper examines memory for language-model agents in organizations, where decisions are recorded across emails, tickets, meeting notes, and documents by multiple authors over months. A changed decision usually creates a new document rather than editing the old one, so a correct answer can depend on the version valid at a particular date.
The authors present Mem++ as a “non-destructive” memory system. It stores each document in full, together with its text, author, event date, embedding, and state, and uses no generative model on the write path. Records are neither deleted nor rewritten; only their state can indicate that a later version superseded them. The goal is to preserve the ability to answer from the original text and all historical versions, unlike systems that extract facts or summaries at ingestion time.
At read time, Mem++ retrieves documents through lexical, author-tag, and semantic paths, then combines rankings with weighted reciprocal-rank fusion. When a question has an as-of date, only active records dated on or before that date enter all three paths. Of the 50 retrieved records used in the main experiments, three slots are reserved for remaining matches with the most recent event dates. The original text, date, and author where available are then passed to the answering model.
The primary evaluation uses the medium tier of OrgMemBench: 443 dated artifacts in 157 threads over 18 months, with 73 questions across six capabilities, including supersession, provenance, bi-temporal reasoning, and justification chains. The main metric is an LLM-judge score using gpt-4o-mini; on OrgMemBench, answers are assessed against 247 rubric facets. The conversational LoCoMo and LongMemEval_S datasets are also used. Comparisons include Full Context, RAG, Mem0, Zep, and, depending on the dataset, methods such as A-Mem, Nemori, and gbrain.
With gpt-4.1-mini, Mem++ obtained an overall OrgMemBench score of 57.6, 2.6 points above RAG and 13.1 points above the strongest compared memory system, A-Mem. With gpt-4o-mini, Mem++ scored 44.2 and its graph variant, Mem_g++, scored 44.4, versus 43.4 for RAG; Mem++ was 8.0 points above the best other memory system, Zep. Mem++ also reported the best average LLM-judge score on LoCoMo with both answer models, but ranked second to its graph variant on LongMemEval_S. In ablations, removing the semantic path caused large drops, including 35.7 points on OrgMemBench.
The limitations matter. The organizational evaluation rests on only 73 questions about one fictional organization; the paper does not report more diverse or real organizational records. In OrgMemBench, only 15 Audit Replay questions have an as-of date, and the answering model sees only the first 40,000 characters of context—about 19 of 50 retrieved rows—so recency-reserve rows and graph triples may not reach the model. Mem_g++ also uses undated triples, which can introduce information from after an as-of date. Its graph benefit was not consistent across answering models.
پژوهشهای بیشتری بخوان
مقالات بیشتر درباره هوش مصنوعی و پژوهشهای تازه را ببین.