از تشخیص عیب تا تصمیم تولید
مدل تشخیص عیب زمانی ارزش عملیاتی دارد که هر هشدار را به شناسه محصول، مالک تصمیم، اقدام بعدی و داده لازم برای ریشهیابی متصل کند.
فهرست مطالب
در بازرسی کیفیت صنعتی، دیدن عیب پایان مسئله نیست؛ آغاز یک زنجیره تصمیم است. یک مدل بینایی ماشین ممکن است ترک، ناپیوستگی سطح، تغییر رنگ یا الگوی غیرعادی را تشخیص دهد، اما تا زمانی که این تشخیص به سرنوشت محصول وصل نشود، خروجی آن فقط یک هشدار دیگر روی یک داشبورد است.
سرنوشت تولیدی یعنی روشن باشد این مشاهده به کدام کویل، شیت، قطعه، بچ یا سفارش مربوط است؛ محصول اکنون در کدام مرحله قرار دارد؛ چه کسی اختیار تصمیم دارد؛ و نتیجه آن تصمیم چه خواهد بود. نگهداشتن، بازبینی، جداسازی، اصلاح، ادامه تولید با کنترل بیشتر یا ثبت برای تحلیل بعدی، هرکدام سرنوشت متفاوتی هستند.
اشتباه رایج این است که پروژه با این سؤال تعریف شود: «آیا مدل عیب را درست تشخیص میدهد؟» این سؤال ضروری است، اما برای انتخاب یا ارزیابی پروژه کافی نیست. سؤال عملیاتیتر این است: «وقتی مدل این عیب را دید، سازمان دقیقاً چه کاری متفاوت انجام میدهد؟»
اگر پاسخ این سؤال مبهم باشد، مسئله احتمالاً هنوز برای اتوماسیون آماده نیست. مدلی که فقط مورد مشکوک را علامت میزند، اما محصول را قابلردیابی و اقدام را قابلمالکیت نمیکند، ممکن است بار بازبینی را جابهجا کند؛ نه اینکه کیفیت یا بهرهوری را بهبود دهد.
در محیط تولید، یک تصویر بهتنهایی زمینه کافی ندارد. هر مشاهده باید دستکم به شناسه یکتای محصول یا ماده، زمان مشاهده، موقعیت فرایندی، ایستگاه یا تجهیز ثبتکننده و وضعیت فعلی محصول متصل باشد. بدون این اتصال، حتی یک تشخیص درست نیز ممکن است به محصول اشتباه نسبت داده شود یا دیر به دست تصمیمگیر برسد.
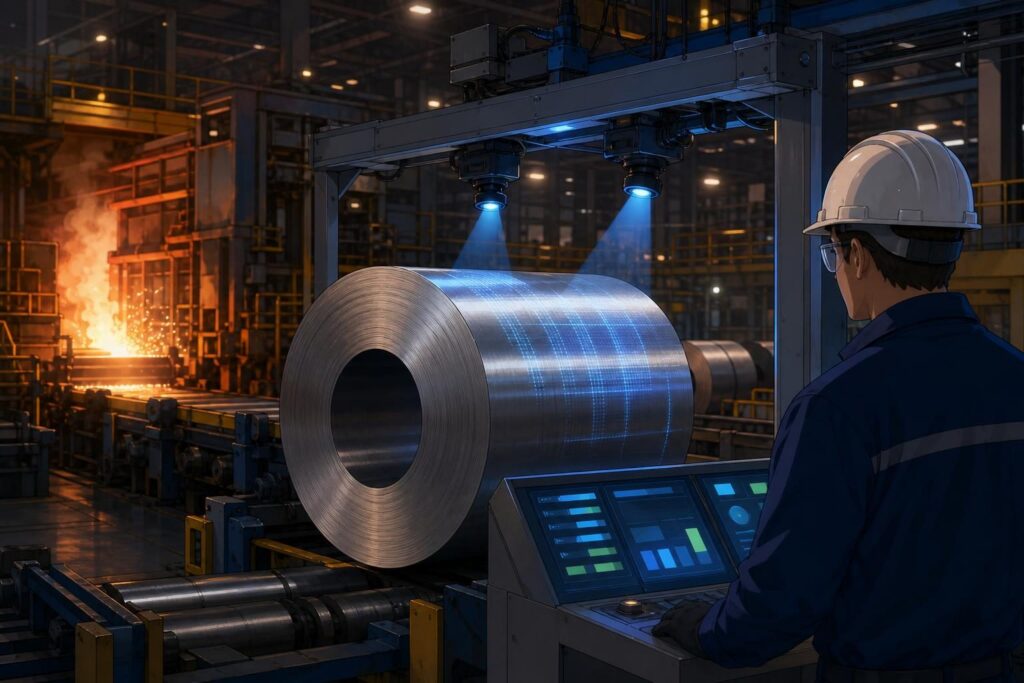
برای مثال فرضی، سامانهای در یک خط نورد نشانهای سطحی را تشخیص میدهد. اگر خروجی فقط تصویر و برچسب «مورد مشکوک» باشد، تیم کیفیت باید جداگانه مشخص کند تصویر به کدام بخش از کدام کویل تعلق دارد، محصول اکنون کجاست و آیا هنوز امکان مداخله وجود دارد یا نه. ارزش مدل در همین فاصله عملیاتی از بین میرود.
در مقابل، یک کارت تصمیم میتواند همان مشاهده را همراه با شناسه کویل، موقعیت طولی، زمان، شدت یا سطح اطمینان مدل، وضعیت خط و مسیر پیشنهادی ثبت کند. هدف کارت تصمیم جایگزینکردن قضاوت انسانی نیست؛ هدف این است که قضاوت در زمان مناسب، با زمینه مناسب و در مسیری قابلممیزی انجام شود.
کارت تصمیم باید با تصمیم شروع شود، نه با فناوری. ابتدا تعیین کنید تصمیم هدف چیست: پذیرش، رد، توقف، کاهش سرعت، نمونهبرداری، بازبینی اپراتور، بازبینی آزمایشگاه یا ایجاد پرونده برای تحلیل ریشهای. سپس مشخص کنید هر تصمیم به چه دادهای نیاز دارد و مدل چه سهمی در تأمین آن خواهد داشت.
مالک تصمیم را نیز باید از ابتدا تعیین کرد. مدل مالک محصول نیست و تیم داده هم نباید ناخواسته مسئول تصمیمهای کیفی یا تولیدی شود. بسته به موضوع، مالک میتواند نقش کنترل کیفیت، سرپرست خط، مهندس فرایند یا مسئول آزمایشگاه باشد. ابهام در مالکیت، هشدارها را به صفهای بیپایان تبدیل میکند.
مرحله بعد، تعریف آستانهها و مسیرهای ارجاع است. همه تشخیصها نباید واکنش یکسان دریافت کنند. برخی موارد میتوانند صرفاً ثبت شوند، برخی باید به بازبینی انسانی بروند و برخی ممکن است نیازمند اقدام فوری باشند. این تمایز باید بر اساس ریسک محصول و فرایند طراحی شود، نه فقط بر مبنای نمره خروجی مدل.
بازبینی انسانی نباید یک عبارت کلی در انتهای طرح باشد. باید روشن باشد بازبین چه چیزی را میبیند، چه زمانی باید پاسخ دهد، با چه شواهدی تصمیم میگیرد و نتیجه را کجا ثبت میکند. اگر بازبین فقط تصویر خام را ببیند، بخش بزرگی از زمینه لازم برای تصمیم درست کنار گذاشته شده است.
همچنین باید مشخص شود کدام بازخوردها واقعاً به بهبود مدل برمیگردند. هر رد یا تأیید انسانی الزاماً داده آموزشی معتبر نیست. بازخورد باید همراه با علت تصمیم، کیفیت تصویر، وضعیت فرایند و سطح اطمینان ثبت شود تا بعداً بتوان میان خطای مدل، خطای داده و تغییر واقعی فرایند تمایز گذاشت.
اتصال تشخیص به دادههای فرایندی، ارزش مهم دیگری نیز دارد: امکان ریشهیابی. وقتی یک الگوی عیب تکرار میشود، سازمان باید بتواند از محصول به رخدادهای فرایند بازگردد؛ مانند تنظیمات تجهیز، تغییر ماده ورودی، وضعیت ابزار، شرایط محیطی یا رخدادهای نگهداری.
این بازگشت از محصول به فرایند، مدل را از یک ابزار هشدار به بخشی از سیستم یادگیری عملیاتی تبدیل میکند. در این حالت، پرسش فقط این نیست که «عیب دیده شد یا نه؟» بلکه این است که «چه شرایطی با ظهور این عیب همراه بودهاند و کدام متغیرها باید بررسی شوند؟»
با این حال، اتصال داده به معنای واردکردن همه دادههای کارخانه به یک پروژه نیست. باید از فرضیه تصمیم شروع کرد. اگر هدف، بررسی شرایط همزمان با افزایش یک عیب مشخص است، فقط دادههایی را وارد کنید که بتوانند آن فرضیه را آزمون یا رد کنند.
گستردگی بیهدف معمولاً قابلیت اتکا را افزایش نمیدهد. برعکس، دامنه بزرگ و تعریفنشده میتواند کیفیت شناسهها، زمانبندی دادهها و مسئولیتپذیری را مبهمتر کند. در پروژههای کیفیت، داده بیشتر زمانی مفید است که مسیر تصمیم را روشنتر کند.
بنابراین معیار موفقیت را فقط با دقت طبقهبندی تعریف نکنید. باید سنجید چه مقدار از هشدارها به یک تصمیم ثبتشده رسیدهاند، چه مقدار در زمان قابلمداخله به مالک تصمیم رسیدهاند، چه مقدار به شناسه درست محصول متصل بودهاند و چه مقدار از پروندهها برای تحلیل ریشهای قابل استفاده بودهاند.
این معیارها ممکن است نقاط ضعف ناخوشایندی را آشکار کنند. شاید مدل از نظر فنی عملکرد قابلقبولی داشته باشد، اما اتصال آن به شناسه محصول ناقص باشد. شاید هشدار بهموقع تولید شود، اما هیچ نقش مشخصی مسئول رسیدگی نباشد. یا شاید تصمیم ثبت شود، اما دلیل آن آنقدر مبهم باشد که چیزی برای بهبود فرایند باقی نماند.
برای شروع، دامنه را کوچک و تصمیم را مشخص نگه دارید. به جای ساخت فهرستی بلند از کاربردهای هوش مصنوعی برای کیفیت، یک عیب محدود، یک نقطه تصمیم، یک مالک و یک حلقه بازخورد انتخاب کنید. چنین محدودهای شکستهای یکپارچهسازی را زودتر آشکار میکند و امکان اصلاح طراحی را پیش از توسعه گسترده فراهم میسازد.
در یک اجرای فرضی، میتوان کار را با عیبی آغاز کرد که هماکنون برای آن مسیر بازبینی دستی وجود دارد. ابتدا همان مسیر را دقیق نقشهبرداری کنید: ورودیها چیستند، چه کسی تصمیم میگیرد، کدام تأخیرها زیانبارند، تصمیم کجا ثبت میشود و چه دادهای برای بررسی علت لازم است.
سپس مدل را فقط در گرهی قرار دهید که واقعاً این جریان را بهتر میکند. ممکن است بهترین نقطه، تشخیص زودتر مورد مشکوک باشد؛ ممکن است اولویتبندی صف بازبینی باشد؛ یا ممکن است تکمیل خودکار زمینهای باشد که بازبین برای تصمیم نیاز دارد. مدل نباید صرفاً به دلیل توانایی فنی، وارد یک مرحله شود.
پیش از تأیید هر پروژه بینایی ماشین برای کیفیت، پنج پرسش را بررسی کنید: تشخیص به کدام شناسه محصول وصل میشود؟ چه کسی و با چه اختیار عملی تصمیم میگیرد؟ هر تصمیم چه اثر مشخصی بر جریان محصول دارد؟ دادههای فرایندی چگونه برای تحلیل علت بازمیگردند؟ و کدام موارد باید صریحاً به انسان ارجاع شوند؟
اگر برای این پرسشها پاسخ اجرایی ندارید، مسئله لزوماً بد نیست؛ فقط هنوز در سطح مدل تعریف شده، نه در سطح عملیات. در این وضعیت، سرمایهگذاری بعدی باید صرف روشنکردن جریان تصمیم، کیفیت شناسهها و مسیر ارجاع شود، نه صرفاً آموزش مدل پیچیدهتر.
جمعبندی روشن است: در کیفیت صنعتی، مدل تشخیص عیب یک جزء است، نه محصول نهایی. محصول واقعی، تصمیمی قابلردیابی است که به سرنوشت مشخصی برای محصول، اقدام روشن برای تیم مسئول و یادگیری قابلاستفاده برای سازمان ختم شود.
In industrial quality inspection, seeing a defect is not the end of the problem; it is the beginning of a decision chain. A computer-vision model may detect a crack, surface discontinuity, color variation, or unusual pattern, but until that detection is connected to the fate of a product, its output is merely another alert on a dashboard.
A production fate means it is clear which coil, sheet, part, batch, or order the observation belongs to; where the product currently sits in the process; who has the authority to decide; and what the outcome of that decision will be. Hold, review, segregate, rework, continue with heightened control, or log for later analysis are all different fates.
A common mistake is to define a project through the question, “Does the model detect the defect correctly?” That question is necessary, but it is not sufficient for selecting or evaluating a project. The more operational question is: “When the model sees this defect, what exactly will the organization do differently?”
If the answer is vague, the problem is probably not ready for automation. A model that only flags suspicious cases, but does not make the product traceable and the action owned, may shift review effort rather than improve quality or productivity.
In a production environment, an image alone does not provide enough context. Every observation should be connected, at minimum, to a unique product or material identifier, observation time, process location, recording station or equipment, and the product’s current status. Without this connection, even a correct detection may be assigned to the wrong product or reach the decision-maker too late.
In a hypothetical example, a system detects a surface indication on a rolling line. If the output is only an image and a “suspicious case” label, the quality team must separately determine which section of which coil the image belongs to, where the product is now, and whether intervention is still possible. The model’s value disappears in that operational gap.
By contrast, a decision card can record the same observation together with the coil identifier, longitudinal position, time, model confidence or severity, line status, and proposed routing. The purpose of a decision card is not to replace human judgment; it is to ensure that judgment happens at the right time, with the right context, through an auditable path.
A decision card should begin with the decision, not the technology. First determine the target decision: accept, reject, stop, slow down, sample, request operator review, request laboratory review, or open a case for root-cause analysis. Then define which data each decision requires and what role the model will play in supplying it.
The decision owner must also be determined from the outset. A model does not own the product, and the data team should not inadvertently become responsible for quality or production decisions. Depending on the issue, ownership may sit with quality control, the line supervisor, a process engineer, or the laboratory lead. Ambiguous ownership turns alerts into endless queues.
The next step is to define thresholds and escalation paths. Not every detection should receive the same response. Some cases can simply be logged, some should go to human review, and some may require immediate action. This distinction should be designed around product and process risk, not only around the model’s output score.
Human review should not be a generic phrase at the end of the design. It should be clear what the reviewer sees, when a response is required, what evidence informs the decision, and where the result is recorded. If the reviewer sees only the raw image, a large part of the context required for a sound decision has been discarded.
It should also be clear which feedback actually returns to improve the model. Not every human rejection or confirmation is valid training data. Feedback should be recorded alongside the decision rationale, image quality, process condition, and confidence level so that model error, data error, and actual process change can later be distinguished.
Connecting detection to process data has another important benefit: root-cause analysis. When a defect pattern repeats, the organization should be able to move back from the product to process events, such as equipment settings, incoming-material changes, tool condition, environmental conditions, or maintenance events.
This return path from product to process turns the model from an alerting tool into part of an operational learning system. The question is no longer only, “Was a defect detected?” It becomes, “Which conditions have accompanied this defect, and which variables should be examined?”
However, connecting data does not mean bringing every factory dataset into one project. Start with a decision hypothesis. If the goal is to examine conditions that coincide with an increase in one specific defect, include only data that can test or challenge that hypothesis.
Unfocused breadth does not usually increase reliability. On the contrary, a broad and undefined scope can make identity quality, data timing, and accountability more ambiguous. In quality projects, more data is useful only when it makes the decision path clearer.
For that reason, do not define success only through classification accuracy. Measure how many alerts reached a recorded decision, how many reached the decision owner while intervention was still possible, how many were linked to the correct product identity, and how many cases were usable for root-cause analysis.
These measures may expose uncomfortable weaknesses. The model may perform acceptably from a technical standpoint while its link to product identity is incomplete. An alert may be generated in time, yet no defined role may be responsible for handling it. Or a decision may be recorded, but its rationale may be so vague that nothing remains to improve the process.
To begin, keep the scope narrow and the decision specific. Rather than building a long list of artificial-intelligence applications for quality, choose one bounded defect, one decision point, one owner, and one feedback loop. This scope reveals integration failures earlier and allows the design to be improved before broad deployment.
In a hypothetical implementation, work can begin with a defect that already has a manual review route. First map that route precisely: what the inputs are, who decides, which delays are harmful, where the decision is recorded, and what data is required to investigate the cause.
Then place the model only at the node where it genuinely improves that flow. The best point may be earlier detection of a suspicious case; it may be prioritizing a review queue; or it may be automatically completing the context a reviewer needs to decide. A model should not be inserted into a stage merely because it is technically capable.
Before approving any computer-vision project for quality, examine five questions: Which product identity does the detection connect to? Who makes the decision, with what operational authority? What specific effect does each decision have on product flow? How does process data return for cause analysis? And which cases must explicitly be referred to a human?
If these questions do not yet have actionable answers, the problem is not necessarily poor; it is simply defined at the model level rather than the operational level. In that situation, the next investment should clarify the decision flow, identity quality, and escalation path, rather than merely train a more complex model.
The conclusion is straightforward: in industrial quality, a defect-detection model is a component, not the final product. The real product is a traceable decision that leads to a defined fate for the product, a clear action for the responsible team, and usable learning for the organization.
اگر این موضوع شبیه مسئله واقعی کسبوکار توست، از چکاپ تصمیم شروع کن.
یک مسیر کوتاه برای روشنکردن مسئله، گلوگاه تصمیم و قدم بعدی؛ بدون فرم طولانی و بدون تعهد.