برای خروجیهای AI، رسید تصمیم بسازید
ارزش AI زمانی قابلسنجش میشود که داده، معیار، تأیید، اقدام و نتیجه هر تصمیم در یک رسید عملیاتی ثبت شود.
فهرست مطالب
بسیاری از تیمها خروجی AI را ذخیره میکنند: پاسخ چت، خلاصه تماس، پیشنهاد قیمت یا برآورد ریسک. این کار برای رجوع بعدی مفید است، اما بهتنهایی نشان نمیدهد AI چه ارزشی ساخته است. پاسخ مدل، تصمیم نیست؛ فقط یکی از ورودیهای تصمیم است.
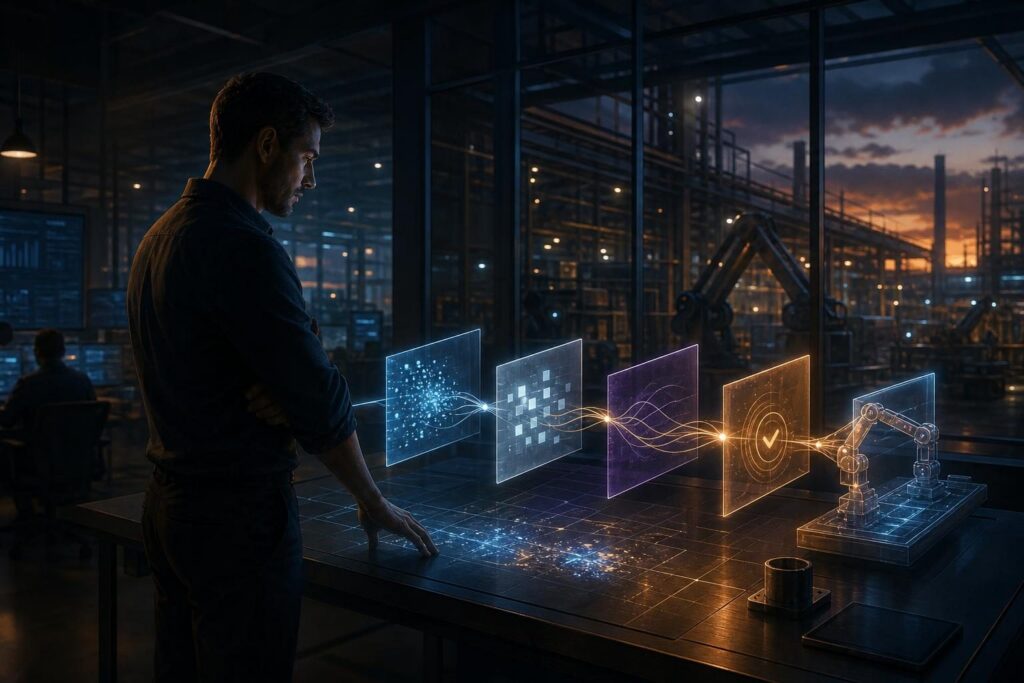
اگر خروجی AI به یک اقدام واقعی منتهی شود، باید بتوان زنجیره آن را بازسازی کرد: چه دادهای در دسترس بود، AI بر چه معیار یا قاعدهای پیشنهاد داد، چه کسی آن را تأیید یا رد کرد، چه اقدامی انجام شد و نتیجه چه بود. این واحد ثبتپذیر را میتوان «رسید تصمیم» نامید.
رسید تصمیم، یک سند طولانی اداری نیست. هدف آن ثبت حداقل اطلاعات لازم برای پاسخدادن به یک پرسش ساده است: آیا این استفاده از AI به تصمیمی بهتر، سریعتر، کمهزینهتر یا قابلاتکاتر منجر شد؟ بدون این زنجیره، پاسخهای خوب و بد هر دو به دادههایی پراکنده تبدیل میشوند.
این موضوع از بحث صرفاً فنی prompt فراتر میرود. کیفیت پاسخ فقط به نحوه نوشتن دستور وابسته نیست؛ وضعیت فرایند، دادههای بیرونی، ابزارهای در دسترس، تاریخچه تعامل و محدودیتهای عملیاتی نیز در آن نقش دارند. اما این زمینه فنی باید در نهایت به زمینه تصمیم و نتیجه کسبوکار وصل شود.
برای این کار، سه لایه زمینه را از هم جدا کنید. لایه اول، زمینه داده است: مدل چه ورودیهایی دید، هر ورودی از کجا آمد و در زمان تصمیم چقدر تازه و کامل بود. ثبت منبع بدون ثبت تازگی کافی نیست، زیرا داده درست اما دیررس میتواند به تصمیم نامناسب منتهی شود.
لایه دوم، زمینه قاعده و معیار است. AI باید برای چه هدفی پیشنهاد بدهد و چه محدودیتهایی را رعایت کند؟ برای مثال، یک دستیار پشتیبانی ممکن است مجاز باشد پاسخ را پیشنویس کند، اما برای تعهد زمانی، تغییر شرایط یا ارجاع موضوع حساس باید معیار روشن و مسیر تأیید داشته باشد.
لایه سوم، زمینه اجرا و نتیجه است. این لایه ثبت میکند که پیشنهاد AI در عمل چه سرنوشتی پیدا کرد: پذیرفته شد، تغییر کرد، رد شد یا به بررسی بیشتر رفت. سپس اقدام نهایی و نتیجه واقعی را به همان رکورد متصل میکند. این بخش، فاصله میان «توصیه خوب به نظر میرسد» و «کار موفق انجام شد» را پر میکند.
یک قالب فشرده برای رسید تصمیم میتواند شامل این فیلدهای ثابت باشد: شناسه تصمیم؛ ورودیها و تازگی آنها؛ توصیه AI؛ معیار یا قاعده تصمیم؛ سطح اختیار؛ مالک تأیید؛ اقدام نهایی؛ نتیجه واقعی؛ و علت رد، اصلاح یا بازکاری. این قالب باید کوتاه بماند، اما هیچ حلقه مهمی از زنجیره تصمیم را حذف نکند.
رسید را با شناسه تصمیم شروع کنید. شناسه باید امکان اتصال رکورد به پرونده، درخواست، سفارش، تیکت یا فرایند مربوط را فراهم کند، بدون آنکه لزوماً داده حساس را در خود رسید تکرار کند. هدف، قابلیت ردیابی است، نه تکثیر بیرویه اطلاعات.
پس از شناسه، ورودیهای مؤثر را ثبت کنید: نام یا نوع منبع، زمان دریافت یا بهروزرسانی، وضعیت کاملبودن و هر محدودیت شناختهشده. اگر دادهای وارد نشده، نامعتبر بوده یا با تأخیر رسیده است، همانجا ثبت شود. نبود داده نیز بخشی از زمینه تصمیم است.
بخش بعدی، توصیه AI است؛ اما فقط متن خام پاسخ را ذخیره نکنید. پیشنهاد را در قالبی عملیاتی ثبت کنید: چه اقدامی پیشنهاد شد، دلیل یا معیار اصلی چه بود، و سطح اطمینان یا ابهام چگونه اعلام شد. سطح اطمینان نباید لزوماً احتمال آماری معتبر مدل تلقی شود؛ این فیلد میتواند برچسبی عملیاتی برای بیان ابهام یا نیاز به بازبینی انسانی باشد.
در کنار توصیه، سطح اختیار را مشخص کنید. بعضی خروجیها فقط برای آگاهیاند، بعضی به تأیید یک مالک فرایند نیاز دارند و بعضی در محدودهای از پیش تعیینشده میتوانند خودکار اجرا شوند. ثبت سطح اختیار، مرز مسئولیت AI، اپراتور و مدیر فرایند را روشن میکند.
مالک تأیید، فیلد ضروری بعدی است. مشخص کنید چه نقش یا فردی مسئول پذیرش، اصلاح یا رد پیشنهاد بوده و وضعیت تأیید چیست. این کار برای سرزنشکردن افراد نیست؛ برای فهمیدن این است که تصمیم در کدام نقطه متوقف شده، تغییر کرده یا به دلیل درست کنترل شده است.
سپس اقدام انجامشده را ثبت کنید. میان پیشنهاد AI و اجرای واقعی تفاوت بگذارید. ممکن است AI پیشنهاد دهد یک درخواست فوراً به تیم دیگری ارجاع شود، اما اپراتور پس از بررسی، اطلاعات تکمیلی بخواهد. این تفاوت باید دیده شود، وگرنه ارزیابی عملکرد AI با ارزیابی عملکرد فرایند مخلوط میشود.
نتیجه واقعی آخرین حلقه رسید است. نتیجه را تا حد ممکن به زبان کار ثبت کنید: آیا مسئله حل شد، آیا نیاز به پیگیری دوباره ایجاد شد، آیا زمان یا هزینه بازکاری صرف شد، و آیا پیامد ناخواستهای رخ داد؟ نتیجه همیشه فوری نیست؛ رسید باید امکان تکمیل یا بهروزرسانی بعدی را داشته باشد.
علت رد، اصلاح یا بازکاری را نیز دستهبندی کنید. دستهها میتوانند شامل داده ناکافی، داده قدیمی، قاعده مبهم، استثنای فرایندی، پیشنهاد نامناسب، نبود اختیار یا اجرای ناقص باشند. این دستهبندی نباید آنقدر پیچیده شود که ثبت را متوقف کند؛ چند علت عملیاتی روشن، معمولاً کافی است.
در یک مثال فرضی، یک سامانه AI در عملیات پیشنهاد میدهد یک درخواست خرید به مسیر عادی برود. رسید تصمیم نشان میدهد که پیشنهاد بر پایه موجودی ثبتشده و سقف مجاز هزینه بوده است. تأییدکننده درخواست را متوقف میکند، زیرا اطلاعات موجودی بهروز نبوده است. نتیجه این نیست که فقط «AI اشتباه کرد»؛ مسئله اصلی، تازگی داده در لایه اول زمینه بوده است.
در مثال فرضی دیگری، AI پیشنویس پاسخ پشتیبانی را درست تولید میکند، اما اپراتور آن را تغییر میدهد چون وعده زمانی پیشنهادی خارج از اختیار اوست. اگر دلیل تغییر ثبت شود، تیم میفهمد مسئله الزاماً کیفیت متن نیست؛ قاعده اختیار و مسیر تأیید باید دقیقتر طراحی شود.
وقتی رسیدها جمع شوند، سنجش ارزش AI از شمار پیامها و توکنها فاصله میگیرد. میتوان دید چه سهمی از پیشنهادها به اقدام رسیدهاند، کجا بیشترین اصلاح رخ میدهد، کدام منبع داده خطای تکرارشونده ایجاد میکند و هزینه بازکاری در کدام مرحله جمع میشود. این سنجهها باید با هدف واقعی همان فرایند تعریف شوند، نه با یک معیار عمومی برای همه کارها.
برای شروع، سراغ همه تصمیمهای سازمان نروید. یک تصمیم پرتکرار، دارای هزینه بازکاری یا حساس به زمان را انتخاب کنید. ابتدا رسید را بهصورت دستی یا نیمهخودکار ثبت کنید، فیلدهای بلااستفاده را حذف کنید و فقط پس از روشنشدن الگوی کار، آن را در ابزارهایی مانند گردشکار، CRM، تیکتینگ یا اتوماسیون پیادهسازی کنید.
رسید تصمیم جای ارزیابی مدل، کنترل کیفیت داده یا نظارت انسانی را نمیگیرد؛ اینها را به یک زنجیره واحد متصل میکند. ارزش AI زمانی قابلحساب میشود که پاسخ، زمینه و اقدام از هم جدا نشوند. اگر نتوانید نشان دهید چه تصمیمی گرفته شد و چه نتیجهای داشت، ذخیرهکردن پاسخها هنوز اثبات ارزش نیست.
Many teams save AI outputs: chat replies, call summaries, pricing suggestions, or risk estimates. That is useful for later reference, but it does not by itself show what value AI created. A model response is not a decision; it is only one input to a decision.
When an AI output leads to real action, the chain should be reconstructable: what data was available, which criterion or rule guided the AI’s recommendation, who approved or rejected it, what action was taken, and what result followed. This recordable unit can be called a “decision receipt.”
A decision receipt is not a long administrative document. Its purpose is to capture the minimum information needed to answer a simple question: did this use of AI lead to a better, faster, less costly, or more reliable decision? Without that chain, good and bad responses alike become scattered data.
This goes beyond the purely technical discussion of prompts. Response quality does not depend only on how an instruction is written; process state, external data, available tools, interaction history, and operating constraints also matter. Yet that technical context must ultimately connect to decision context and business outcomes.
To do this, separate three layers of context. The first is data context: which inputs the model saw, where each input came from, and how current and complete it was at the time of the decision. Recording a source without recording freshness is not enough, because accurate but delayed data can still produce an unsuitable decision.
The second layer is rule and criteria context. What objective should the AI support, and what constraints must it respect? For example, a support assistant may be allowed to draft a response, while commitments about timing, changed terms, or sensitive escalation require clear criteria and an approval path.
The third layer is execution and outcome context. It records what happened to the AI recommendation in practice: it was accepted, changed, rejected, or sent for further review. It then links the final action and the actual outcome to the same record. This fills the gap between “the recommendation looks good” and “the work was completed successfully.”
A compact decision-receipt template can include these fixed fields: decision identifier; inputs and their freshness; AI recommendation; decision criterion or rule; authority level; approval owner; final action; actual outcome; and reason for rejection, modification, or rework. The template should remain short while retaining every important link in the decision chain.
Start the receipt with a decision identifier. The identifier should make it possible to connect the record to the relevant case, request, order, ticket, or process without necessarily duplicating sensitive data inside the receipt. The goal is traceability, not uncontrolled replication of information.
After the identifier, record the material inputs: the source name or type, the time it was received or updated, its completeness status, and any known limitation. If data was missing, invalid, or delayed, record that as well. Missing data is also part of a decision’s context.
The next section is the AI recommendation, but do not save only the raw response text. Record the recommendation in an operational form: what action was proposed, what main reason or criterion supported it, and how confidence or uncertainty was communicated. Confidence should not necessarily be treated as a valid statistical probability; this field can be an operational label for uncertainty or the need for human review.
Alongside the recommendation, define the authority level. Some outputs are informational only, some require approval by a process owner, and some can be executed automatically within a predefined boundary. Recording authority clarifies the responsibility boundary among AI, the operator, and the process manager.
The approval owner is the next essential field. Specify which role or person was responsible for accepting, modifying, or rejecting the recommendation, and record the approval status. This is not for blaming people; it is for understanding where a decision stopped, changed, or was correctly controlled.
Then record the action actually taken. Distinguish between the AI recommendation and real execution. An AI may suggest immediately routing a request to another team, while an operator may request additional information after review. That difference must be visible; otherwise, evaluating AI performance becomes mixed up with evaluating process performance.
The actual outcome is the final link in the receipt. Capture it, as far as possible, in the language of the work: was the issue resolved, did it require follow-up, was time or cost spent on rework, and did any unintended consequence occur? Outcomes are not always immediate, so the receipt should allow later completion or updates.
Also categorize the reason for rejection, modification, or rework. Categories may include insufficient data, stale data, an ambiguous rule, a process exception, an unsuitable recommendation, lack of authority, or incomplete execution. The classification should not become so complex that it prevents recording; a few clear operational reasons are usually enough.
In one hypothetical example, an AI system in operations suggests that a purchase request should follow the standard route. The decision receipt shows that the suggestion relied on recorded inventory and an authorized spending limit. The approver stops the request because the inventory information is not current. The conclusion is not simply that “AI was wrong”; the primary issue was data freshness in the first context layer.
In another hypothetical example, an AI correctly drafts a support response, but the operator changes it because the proposed timing commitment exceeds their authority. If the reason for the change is recorded, the team learns that the issue is not necessarily writing quality; the authority rule and approval path need more precise design.
As receipts accumulate, measuring AI value moves away from message and token counts. You can see what share of recommendations reached action, where the most edits occur, which data source creates recurring errors, and at which stage rework costs accumulate. These measures should be defined around the real objective of that process, not around one generic metric for every task.
To begin, do not attempt every decision in the organization. Choose one recurring decision with rework cost or time sensitivity. First capture the receipt manually or semi-automatically, remove fields that go unused, and only after the working pattern is clear, implement it in tools such as workflow systems, CRM, ticketing, or automation.
A decision receipt does not replace model evaluation, data-quality control, or human oversight; it connects them in one chain. AI value becomes accountable when the response, context, and action are not separated. If you cannot show what decision was made and what outcome it produced, saving responses is still not proof of value.
اگر این موضوع شبیه مسئله واقعی کسبوکار توست، از چکاپ تصمیم شروع کن.
یک مسیر کوتاه برای روشنکردن مسئله، گلوگاه تصمیم و قدم بعدی؛ بدون فرم طولانی و بدون تعهد.