قرارداد اجرایی استثنا: از توقف کنترلشده تا بازاجرایی امن
workflow هوشمند با افزودن یک تأیید انسانی قابلاعتماد نمیشود. هر استثنا به قرارداد اجرایی نیاز دارد: منشأ، مالک تصمیم، داده لازم، اختیار اصلاح، بازاجرایی امن و شرط روشن بازگشت.
فهرست مطالب
در workflowهای مبتنی بر هوش مصنوعی، استثنا فقط نشانه شکست نیست. اغلب نشان میدهد فرایند با وضعیتی روبهرو شده که قواعد، دادهها یا اختیارهای موجود برای آن کافی نبودهاند. داده ناقص، تعارض میان دو سیاست، ابهام در خروجی مدل، خطای اتصال به ابزار یا درخواست پرریسک، همگی میتوانند جریان عادی کار را متوقف کنند.
مسئله اصلی در چنین وضعیتی صرفاً متوقفکردن workflow نیست. مسئله این است که سازمان بداند پس از توقف، چه کسی باید تصمیم بگیرد، با چه اطلاعاتی تصمیم بگیرد، چه چیزی را مجاز است اصلاح کند و چگونه جریان کار بدون ایجاد اثر تکراری یا مخرب از سر گرفته شود.
افزودن یک مرحله تأیید انسانی بهتنهایی این مسئله را حل نمیکند. اگر مشخص نباشد تأییدکننده چه اطلاعاتی میبیند، دامنه اختیار او چیست، پس از تصمیم او کدام مرحله دوباره اجرا میشود و چه کنترلی از اجرای تکراری جلوگیری میکند، تأیید انسانی فقط یک گلوگاه تازه میسازد.
صفی که تصمیم روشن تولید نکند، استثنا را مدیریت نمیکند؛ فقط زمان توقف آن را طولانیتر میکند. به همین دلیل، هر دسته استثنا به یک «قرارداد اجرایی» نیاز دارد: مجموعهای از قواعد عملیاتی که از لحظه تشخیص تا بازگشت به جریان عادی، مسیر تصمیم و اجرا را روشن میکند.
قرارداد اجرایی استثنا یک سند تزئینی یا صرفاً حقوقی نیست. این قرارداد تعیین میکند استثنا از کجا ثبت میشود، چه شواهدی باید همراه آن باشد، مالک تصمیم چه کسی است، چه نوع اصلاحی مجاز است، بازاجرایی چگونه انجام میشود و چه شرطی اجازه بازگشت به مسیر عادی را میدهد.
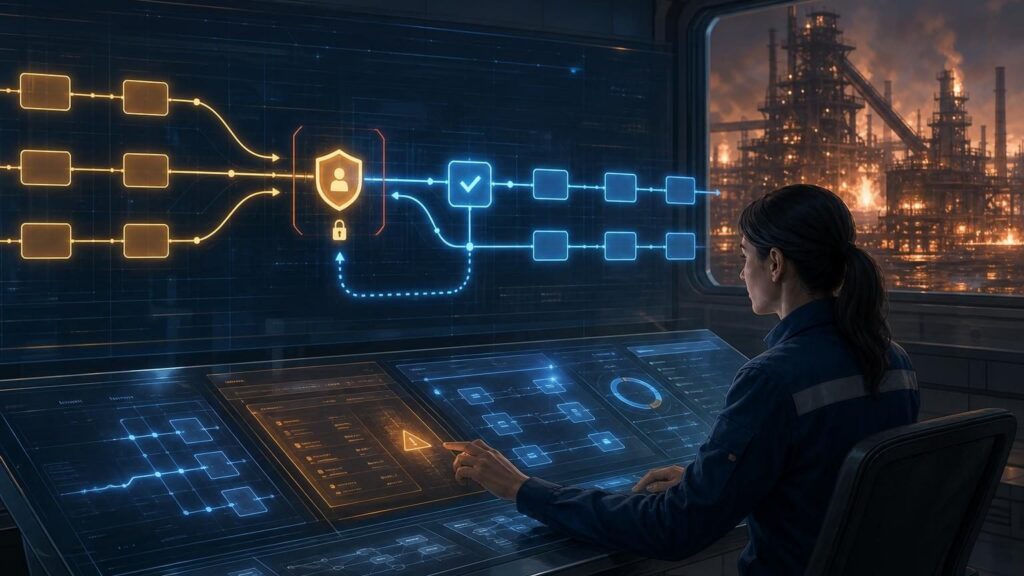
چرخهعمر استثنا را میتوان در هفت گام دید: تشخیص، طبقهبندی، توقف یا محدودسازی، تخصیص به مالک تصمیم، اصلاح، بازاجرایی امن و ارزیابی شرط بازگشت. هر گام باید در داده اجرای workflow قابل مشاهده باشد. اگر یک مورد از صف خارج شود اما علت خروج، تصمیم ثبتشده و نتیجه بازاجرایی آن معلوم نباشد، وضعیت فقط از یک کانال به کانال دیگر منتقل شده است.
نقطه شروع، یک schema استاندارد برای رکورد استثناست. این رکورد میتواند شامل شناسه اجرای workflow، زمان تشخیص، مرحله وقوع مسئله، نوع استثنا، سطح اثر، دادههای ورودی مرتبط، خروجی یا خطای مشاهدهشده، شناسه مالک تصمیم، وضعیت فعلی و پیوند به ردپای اجرا باشد.
هدف از ثبت این دادهها، انباشتن همه اطلاعات ممکن نیست. هدف، فراهمکردن حداقل شواهد لازم برای تصمیمی قابلپیگیری است. اگر تصمیمگیرنده برای فهم وضعیت مجبور باشد میان پیامها، فایلها، داشبوردها و نسخههای متعدد داده جستوجو کند، خود صف استثنا به منبع جدیدی از خطا و تأخیر تبدیل میشود.
طبقهبندی استثنا باید میان خطای فنی و تصمیم کسبوکاری تمایز بگذارد. قطع موقت یک API، پایان زمان پاسخ یا محدودیت نرخ، معمولاً به سیاست retry فنی نیاز دارد. اما ابهام در مشخصات سفارش، تعارض میان محدودیت اعتباری و پیشنهاد فروش، یا هشدار کیفیتی که با داده تولید سازگار نیست، تصمیم کسبوکاری است.
آمیختن این دو دسته پیامد نامطلوب دارد. یا انسانها برای خطاهای ساده و قابلبازیابی فراخوانده میشوند، یا سامانه درباره تصمیمهای حساس و دارای اثر بیرونی خودسرانه عمل میکند. قرارداد اجرایی باید مشخص کند کدام مورد با retry حل میشود، کدام مورد توقف میخواهد و کدام مورد باید به نقش دارای اختیار منتقل شود.
برای retry فنی، قرارداد باید تعداد تلاش مجاز، فاصله میان تلاشها، شرط توقف و مسیر escalation را مشخص کند. retry نباید به معنای تکرار بیپایان یک درخواست باشد. وقتی خطای فنی از آستانه تعریفشده عبور میکند، باید به استثنای عملیاتی تبدیل شود و مالک مشخصی داشته باشد.
در این مرحله، اطلاعاتی مانند پیام خطا، وضعیت ابزار، ورودی درخواست، زمان وقوع و سابقه تلاشها برای تشخیص لازم است. اما این اطلاعات باید همراه با زمینه عملیاتی ارائه شوند. یک خطای فنی بدون دانستن اینکه اجرای آن قرار بوده چه اثر تجاری یا عملیاتی ایجاد کند، برای تصمیمگیری کافی نیست.
استثنای کسبوکاری به زبان متفاوتی نیاز دارد. مالک تصمیم نباید فقط دکمه «تأیید» یا «رد» ببیند. او باید بداند workflow چه اقدامی را پیشنهاد کرده، چرا آن اقدام متوقف شده، کدام داده یا سیاست با آن در تعارض است و چه گزینههایی برای ادامه مجاز هستند.
طراحی خوب، دامنه تصمیم را محدود و روشن میکند: تأیید، رد، اصلاح یک فیلد مشخص، درخواست اطلاعات تکمیلی یا ارجاع به سطح اختیار بالاتر. این محدودسازی به معنای حذف قضاوت انسانی نیست؛ به معنای تبدیل قضاوت به تصمیمی ثبتپذیر، قابلاجرا و قابلممیزی است.
هر اقدامی که اثر بیرونی، مالی، حقوقی، ایمنی یا عملیاتی دارد، باید پیش از اجرا مرز تصمیم صریح داشته باشد. راهنمای OpenAI درباره guardrails و approvals نیز میان کنترل خودکار، توقف برای تأیید انسانی و انتقال کنترل در شرایط مشخص تمایز میگذارد. این تمایز باید در معماری workflow دیده شود، نه اینکه فقط به یک دکمه تأیید در انتهای فرایند محدود بماند.
صف بازبینی نباید صندوق ورودی مشترک و بیمالک باشد. برای هر نوع استثنا، یک نقش مسئول، یک نقش جانشین، زمان هدف برای تصمیم و قاعده escalation لازم است. زمان هدف وعده پاسخ فوری نیست؛ ابزاری است برای آشکارکردن مواردی که بدون تصمیم باقی ماندهاند.
اختیار اصلاح نیز باید از اختیار تصمیم جدا شود. ممکن است یک نقش کیفیت اجازه داشته باشد علت هشدار را طبقهبندی کند، اما اجازه تغییر داده مرجع محصول را نداشته باشد. ممکن است نقش فروش بتواند پیشنهاد قیمت را برای بازبینی برگرداند، اما نتواند محدودیت اعتباری را نادیده بگیرد.
قرارداد اجرایی باید دقیقاً مشخص کند هر نقش کدام فیلدها، کدام تصمیمها و کدام عملیات بازاجرایی را میتواند انجام دهد. این تفکیک، هم از گسترش بیضابطه اختیار جلوگیری میکند و هم تعیین میکند مسئولیت هر تغییر در کجا ثبت شود.
پس از اصلاح، خطر اصلی بازاجرایی مخرب است. اگر workflow پیش از توقف بخشی از کار را انجام داده باشد، اجرای کامل آن از ابتدا میتواند پیام تکراری ارسال کند، سفارش مضاعف ثبت کند یا یک عملیات بیرونی را دوباره آغاز کند. بازگشت به جریان باید با شناسههای پایدار، وضعیت مرحلهها و کلید idempotency طراحی شود.
کلید idempotency باید به یک واحد مشخص از اثر عملیاتی متصل باشد، نه فقط به کل اجرای workflow. در یک مثال فرضی، ارسال درخواست خرید، ثبت هشدار نگهداری یا تغییر وضعیت سفارش، هر کدام باید کلیدی داشته باشند که سامانه مقصد با آن تشخیص دهد درخواست دارای همان اثر پیشتر پذیرفته شده است یا نه.
بازاجرایی نیز نباید همیشه از نخستین گام آغاز شود. قرارداد باید تعیین کند کدام مرحله checkpoint معتبر است، چه دادهای از اجرای قبلی قابل استفاده است و کدام خروجی باید دوباره تولید شود. مستندات n8n مشاهده دادههای اجرا و بازاجرایی را توضیح میدهند؛ پیش از تکیه بر داده ذخیرهشده نیز باید در دسترسبودن آن را با تنظیمات نگهداری داده بررسی کرد.
بازگشت به مسیر عادی نیازمند شرطی روشن و قابلارزیابی است. «انسان بررسی کرد» شرط بازگشت نیست. شرط مناسب میتواند تکمیل یک فیلد اجباری، رفع تعارض میان دو منبع داده، تصویب یک استثنای سیاستی توسط نقش مجاز یا دریافت پاسخ معتبر از ابزار باشد.
سنجهها نیز باید رفتار عملیاتی را نشان دهند، نه فقط تعداد خطاها را. زمان تا تصمیم، نرخ بازگشت موفق، نرخ تکرار استثنا، نرخ escalation و سهم مواردی که ردپای تصمیم کامل دارند، میتوانند کیفیت چرخه استثنا را آشکار کنند. این سنجهها باید برای اصلاح داده، سیاست، طراحی prompt یا معماری ابزار به کار روند، نه فقط برای گزارشگیری.
برای یک نمونه فرضی در صنعت فولاد، سامانهای را تصور کنید که بر پایه داده کیفیت و برنامه تولید، اولویت سفارش را پیشنهاد میدهد؛ اما گواهی کیفیت ورودی با مشخصات ثبتشده سفارش ناسازگار است. قرارداد استثنا باید اجرای خودکار پیشنهاد را متوقف کند، داده و سیاست متعارض را به نقش مناسب نشان دهد، گزینه اصلاح مجاز را مشخص کند و فقط پس از رفع ناسازگاری یا تصویب استثنا، ادامه برنامه را از checkpoint تعریفشده ممکن سازد.
پیادهسازی مرحلهای در n8n یا ابزار مشابه میتواند با سه جریان آغاز شود: ثبت ساختیافته استثنا، صف تصمیم انسانی و workflow بازاجرایی. سپس میتوان سیاست retry، کلیدهای idempotency، ثبت تغییرات و داشبورد سنجهها را اضافه کرد. workflow قابلاعتماد با حذف استثنا ساخته نمیشود؛ با تبدیل هر استثنا به مسیر تصمیمپذیر، قابلاجرا، قابلممیزی و دارای شرط روشن برای بازگشت ساخته میشود.
In AI-based workflows, an exception is not only a sign of failure. It often indicates that the process has encountered a situation for which the available rules, data, or authorities are insufficient. Incomplete data, conflict between two policies, ambiguity in a model output, a tool integration failure, or a high-risk request can all interrupt the normal flow of work.
The central issue in such a situation is not merely stopping the workflow. The issue is whether the organization knows who should decide after the pause, what information they need, what they are authorized to amend, and how the workflow can resume without creating duplicate or harmful effects.
Adding a human approval step alone does not solve this problem. If it is unclear what information the approver sees, what their authority scope is, which stage runs again after their decision, and what control prevents repetition, human approval simply creates another bottleneck.
A queue that does not produce a clear decision does not manage an exception; it only extends the interruption. This is why every exception category needs an execution contract: a set of operational rules that clarifies the path of decision and execution from detection through return to normal flow.
An exception execution contract is neither decorative documentation nor merely a legal artifact. It defines where an exception is recorded, what evidence must accompany it, who owns the decision, what remediation is permitted, how re-execution occurs, and what condition permits a return to the normal path.
An exception lifecycle can be viewed in seven steps: detection, classification, stopping or limiting the process, assignment to a decision owner, remediation, safe re-execution, and evaluation of the return condition. Every step should be visible in the workflow execution data. If a case leaves the queue but its exit reason, recorded decision, and re-execution result are unknown, the situation has merely been moved from one channel to another.
The starting point is a standard schema for the exception record. It can include the workflow execution identifier, detection time, the stage where the issue occurred, exception type, impact level, relevant input data, the observed output or error, the decision owner identifier, current status, and a link to the execution trail.
The purpose of recording this data is not to accumulate every possible piece of information. It is to provide the minimum evidence required for a traceable decision. If the decision-maker must search through messages, files, dashboards, and multiple data versions to understand the situation, the exception queue itself becomes a new source of error and delay.
Exception classification must distinguish a technical failure from a business decision. A temporary API outage, timeout, or rate limit usually requires a technical retry policy. Ambiguity in an order specification, a conflict between a credit restriction and a sales proposal, or a quality alert that conflicts with production data, however, is a business decision.
Mixing these two categories has an undesirable result. Either people are called into simple and recoverable technical failures, or the system acts autonomously on sensitive decisions with external consequences. The execution contract should specify which cases are resolved through retry, which require a pause, and which must be transferred to a role with authority.
For technical retries, the contract should specify the permitted number of attempts, the interval between attempts, the stopping condition, and the escalation path. Retry must not mean endlessly repeating a request. When a technical failure passes its defined threshold, it should become an operational exception with a named owner.
At that point, information such as the error message, tool status, request input, occurrence time, and attempt history is needed for diagnosis. However, this information should be presented with operational context. A technical error is not sufficient for a decision if it is unknown what business or operational effect the execution was intended to create.
A business exception requires a different language. The decision owner should not see only Approve or Reject buttons. They should know what action the workflow proposed, why that action was halted, which data or policy conflicts with it, and what options are permitted for continuation.
Good design constrains and clarifies the decision range: approve, reject, amend a specified field, request additional information, or escalate to a higher authority level. This constraint does not eliminate human judgment; it turns that judgment into a decision that can be recorded, executed, and audited.
Any action with external, financial, legal, safety, or operational consequences should have an explicit decision boundary before execution. OpenAI guidance on guardrails and approvals also distinguishes automated control, a pause for human approval, and transfer of control under defined conditions. This distinction should appear in workflow architecture rather than being limited to an approval button at the end of a process.
A review queue must not be an unowned shared inbox. Each exception type requires an accountable role, a backup role, a target decision time, and an escalation rule. A target time does not promise an immediate response; it is a tool for identifying cases that remain without a decision.
Authority to remediate should also be separated from authority to decide. A quality role may be allowed to classify the cause of an alert but not to change master product data. A sales role may be able to return a price proposal for review but not to override a credit restriction.
The execution contract should state precisely which fields, decisions, and re-execution operations each role can perform. This separation both prevents uncontrolled expansion of authority and establishes where responsibility for each change is recorded.
After remediation, harmful re-execution becomes the main risk. If the workflow completed part of its work before stopping, rerunning the full flow from the beginning can send duplicate messages, create duplicate orders, or initiate an external operation again. Return to flow should be designed with stable identifiers, stage states, and idempotency keys.
An idempotency key should be connected to a defined unit of operational effect, not merely to the entire workflow execution. In a hypothetical example, submitting a purchase request, creating a maintenance alert, or changing an order status should each have a key that lets the destination system determine whether a request with the same effect has already been accepted.
Re-execution should not always start at the first step. The contract should define which stage is a valid checkpoint, what data from the prior execution can be reused, and which output must be generated again. n8n documentation describes execution-data visibility and re-execution; before relying on stored data, teams should verify that it is available under their data-retention settings.
Returning to normal flow requires an explicit and testable condition. Human review completed is not a return condition. An appropriate condition may be completion of a required field, resolution of a conflict between two data sources, approval of a policy exception by an authorized role, or receipt of a valid tool response.
Metrics should also reveal operational behavior rather than merely count errors. Time to decision, successful return rate, exception recurrence rate, escalation rate, and the share of cases with a complete decision trail can reveal the quality of the exception lifecycle. These metrics should support improvements in data, policy, prompt design, or tool architecture, rather than serve reporting alone.
For a hypothetical steel-industry example, consider a system that proposes order priority using quality data and the production schedule, while the incoming quality certificate conflicts with the order specifications on record. The exception contract should stop automatic execution of the proposal, show the conflicting data and policy to the appropriate role, identify the permitted remediation option, and allow the plan to continue from a defined checkpoint only after the inconsistency is resolved or the exception is approved.
A phased implementation in n8n or a similar tool can begin with three flows: structured exception logging, a human decision queue, and a re-execution workflow. Retry policies, idempotency keys, change logging, and metric dashboards can then be added. A reliable workflow is not built by eliminating exceptions; it is built by turning every exception into a decisionable, executable, auditable path with a clear condition for return.
اگر این موضوع شبیه مسئله واقعی کسبوکار توست، از چکاپ تصمیم شروع کن.
یک مسیر کوتاه برای روشنکردن مسئله، گلوگاه تصمیم و قدم بعدی؛ بدون فرم طولانی و بدون تعهد.