هر تأییدی کنترل نیست؛ صف تصمیم درست برای AI را طراحی کنید
کنترل انسانی در AI با یک دکمه تأیید ساخته نمیشود؛ با صف درست، آستانه روشن، شواهد کافی و مسیر اعتراض ساخته میشود.
فهرست مطالب
خیلی از جریانهای کاری AI با یک سوءتفاهم طراحی میشوند: اگر در انتهای کار دکمه «تأیید» گذاشتهایم، پس انسان همچنان کنترل را در دست دارد. در عمل، این دکمه اغلب فقط آخرین ایستگاه یک فرایند مبهم است؛ جایی که بازبین باید در چند ثانیه تصمیمی را امضا کند که زمینهاش را ندیده، پیامدش را نمیداند و فرصت بررسی واقعیاش را هم ندارد.
تأییدِ انسانی، بهخودیخود کنترل نیست. گاهی فقط انتقال مسئولیت است. سیستم پیشنهادش را تولید میکند، کاربر خسته یا گرفتار آن را تأیید میکند و وقتی مسئلهای پیش میآید، همه میگویند «انسان که تأیید کرده بود». این مدل نه به AI انضباط میدهد و نه به انسان اختیار واقعی.
کنترل واقعی خیلی زودتر از دکمه تأیید شروع میشود: از این سؤال که کدام تصمیم اصلاً باید به انسان برسد. همه خروجیها ارزش بازبینی انسانی ندارند. اگر هر موردی را به صف بفرستید، صف شلوغ میشود، تمرکز از بین میرود و بازبین بهتدریج یاد میگیرد فقط روی «تأیید» کلیک کند. این همان خستگی تأیید است، یعنی حالتی که تکرار زیاد درخواستهای تأیید، دقت و حساسیت بازبین را پایین میآورد؛ خطری که آرام و بیسروصدا کیفیت کنترل را کم میکند.
در مقابل، اگر هیچ چیز به انسان ارجاع نشود، اتوماسیون در جایی اختیار میگیرد که هنوز شایستگی آن را ندارد. مسئله، انتخاب بین کنترل کامل انسانی و خودکاری کامل نیست. مسئله این است که مرز تصمیم را طوری طراحی کنیم که ماشین کارهای روشن، کمریسک و برگشتپذیر را جلو ببرد و انسان مالک ابهام، ریسک و پیامدهای سختبرگشت باشد.
برای شروع، یک جریان کاری واقعی را انتخاب کنید؛ نه یک نقشه آرمانی روی وایتبرد. مثلاً فرض کنید AI قرار است تغییر پیشنهادی در برنامه تولید را بررسی کند، مغایرت کیفیت را اعلام کند یا برای دسترسی به داده حساس پیشنهاد اقدام بدهد. سپس تصمیمها را از هم جدا کنید. «تحلیل داده»، «پیشنهاد اقدام» و «اجرای اقدام» یک تصمیم نیستند، حتی اگر در یک گردش کار کنار هم قرار گرفته باشند.
در هر مرحله بپرسید: اگر سیستم اشتباه کند، چه چیزی از دست میرود؟ آیا این خطا قابل بازگشت است؟ آیا اثر آن فقط داخلی است یا به مشتری، کیفیت، ایمنی، تعهد قراردادی یا داده حساس میرسد؟ آیا AI بر اساس اطلاعات کامل تصمیم میگیرد یا با دادهای ناقص و متغیر روبهروست؟ پاسخ این سؤالها باید تعیین کند که مورد خودکار عبور کند، وارد صف بازبینی شود یا از ابتدا متوقف بماند.
آستانه ارجاع نباید فقط یک امتیاز اطمینان باشد. مدل ممکن است با اطمینان بالا هم اشتباه کند، مخصوصاً وقتی مسئله خارج از دادههای آشناست. آستانه بهتر، ترکیبی است از میزان اطمینان، شدت پیامد، برگشتپذیری، حساسیت داده، ارزش مالی یا عملیاتی، و وجود نشانههای غیرعادی در ورودی. هرچه تصمیم گرانتر یا سختتر برای جبران باشد، دلیل بیشتری برای ارجاع انسانی دارید.
یک قاعده ساده به کار میآید: AI میتواند پیشنهاد دهد؛ اما وقتی تصمیم هم مبهم است و هم پرهزینه، نباید تنها اجرا کند. این قاعده عمداً ساده است، چون هدفش ساختن مدل کامل ریسک نیست. هدف این است که تیم از بحث کلی «انسان در حلقه باشد» خارج شود و برای هر تصمیم، حق اجرا را صریح تعیین کند.
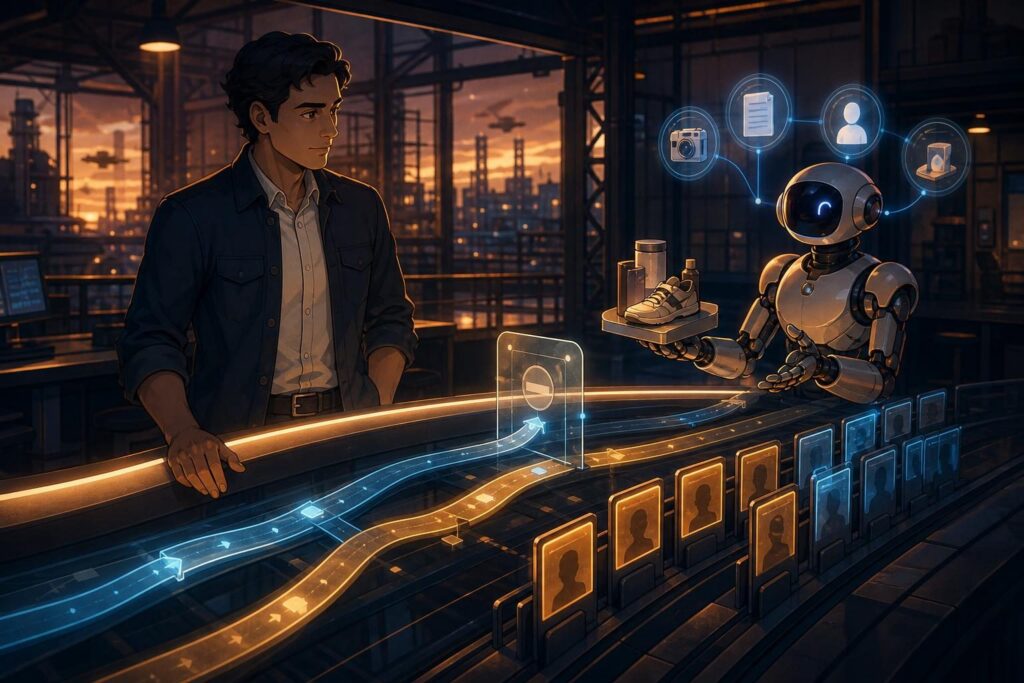
اما صف بازبینی فقط محل جمع شدن کارها نیست. صف، محصول عملیاتی شماست. اگر بازبین نداند چرا این مورد به او رسیده، چه گزینههایی دارد و پاسخ او چه اثری میگذارد، حتی بهترین سیاست ارجاع هم در اجرا شکست میخورد. کسی که فقط یک پیشنهاد و دو دکمه ببیند، معمولاً سریعترین مسیر را انتخاب میکند، نه مسئولانهترین مسیر را.
هر مورد در صف باید یک بسته تصمیم داشته باشد. این بسته لازم نیست طولانی و نمایشی باشد، اما باید مسئله را قابل قضاوت کند: پیشنهاد AI چیست، بر چه شواهدی تکیه کرده، چه دادهای ناقص یا متناقض بوده، سطح ریسک چیست، چه اقدامی قرار است انجام شود و اگر اقدامی نکنیم چه اتفاقی میافتد. بازبین نباید برای فهمیدن زمینه، میان چند سیستم سرگردان شود.
کنار پیشنهاد، گزینهها را واقعی طراحی کنید. تأیید، رد و اصلاح حداقل گزینهها هستند. گاهی تعویق، درخواست اطلاعات بیشتر یا ارجاع به نقش دیگر هم لازم است. مهمتر از تعداد دکمهها، معنای آنهاست. «رد» باید بتواند جریان را متوقف کند؛ «اصلاح» باید تغییر انسان را ثبت کند؛ و «ارجاع» باید مالک بعدی، دلیل ارجاع و زمان پیگیری داشته باشد.
اگر رد کردن یک پیشنهاد هزینه اجتماعی یا عملیاتی زیادی داشته باشد، بازبین در عمل رد نمیکند. مثلاً وقتی رد به معنای شروع دوباره یک فرایند طولانی است، یا وقتی هیچکس نمیفهمد چرا مورد رد شده، تأیید به انتخاب پیشفرض تبدیل میشود. طراحی درست باید مخالفت مسئولانه را آسانتر کند، نه اینکه فقط تأیید را ساده کند.
همینجا حق اعتراض معنا پیدا میکند. اعتراض فقط برای مشتری یا مدیر نیست. کارشناس بازبین باید بتواند بگوید شواهد کافی نیست، طبقهبندی مسئله غلط است، ریسک کمبرآورد شده یا اساساً این مورد نباید در این صف میآمد. این اعتراض نباید در یادداشتهای پراکنده گم شود. باید بخشی از گردش کار باشد و به بازطراحی قاعده یا داده ورودی راه پیدا کند.
زمان نیز بخشی از کنترل است. صفی که زمان پاسخ ندارد، یا در انتظار میماند یا زیر فشار لحظه آخر به تأییدهای بیدقت میرسد. برای هر نوع تصمیم، زمان پاسخ مورد انتظار تعیین کنید. موارد فوری باید مسیر روشن و محدود داشته باشند؛ موارد عادی نباید بیدلیل با اعلانهای پیدرپی مزاحم همه شوند. اضطرار دائمی، همان بینظمی با صدای بلند است.
برای مواردی که در زمان مشخص پاسخ نمیگیرند، مسیر جایگزین لازم است. اما ارجاع خودکار به مدیر راهحل عمومی نیست. مدیر معمولاً زمینه عملیاتی را ندارد و به گلوگاه تبدیل میشود. بهتر است برای هر نوع تصمیم، نقش جایگزین مشخص باشد: فردی که هم اختیار دارد، هم توان قضاوت، و هم میداند پذیرش تصمیم چه مسئولیتی ایجاد میکند.
در یک سناریوی صنعتی، فرض کنید سیستم مغایرتی را در کیفیت محصول تشخیص داده و پیشنهاد میکند محموله نگه داشته شود. این تصمیم نباید فقط با یک برچسب «اعتماد بالا» به مسئول کیفیت برسد. او باید ببیند کدام دادهها با الگوی معمول نمیخوانند، دامنه احتمالی اثر چیست، چه محمولهها یا سفارشهایی درگیرند، و آیا پیشنهاد جایگزینی مثل نمونهبرداری مجدد یا محدود کردن ارسال وجود دارد یا نه.
اگر مسئول کیفیت پیشنهاد را اصلاح کند و بهجای توقف کامل، بازرسی تکمیلی را انتخاب کند، این فقط یک استثنا نیست. یک قطعه داده ارزشمند است. سیستم باید ثبت کند AI چه گفته، انسان چه تغییری داده، چرا تغییر داده و نتیجه واقعی چه بوده است. بدون این رد تصمیم، سازمان فقط میفهمد چه کاری انجام شده؛ نمیفهمد چرا قاعده قبلی برای قضاوت کافی نبوده است.
این ثبت، برای سرزنش بازبین نیست. اگر ثبت تصمیم به ابزار نظارت فردی تبدیل شود، آدمها یا توضیح نمینویسند یا توضیحهای بیفایده مینویسند. هدف، یادگیری عملیاتی است: کدام آستانهها بد تنظیم شدهاند، کدام شواهد کماند، کدام دسته از موارد بیش از حد ارجاع میشوند، و کجا AI یا فرایند انسانی نیاز به اصلاح دارد.
کیفیت همکاری انسان و AI را با تعداد تأییدها نسنجید. نرخ رد یا اصلاح، زمان رسیدگی، حجم موارد معطل، تعداد ارجاعهای دوباره، درصد تصمیمهای برگشتی و الگوی اعتراضها معمولاً چیزهای بیشتری به شما میگویند. نرخ رد بالا الزاماً بد نیست؛ شاید نشان دهد صف بهدرستی موارد پیچیده را گرفته است. نرخ رد نزدیک صفر هم الزاماً خوب نیست؛ شاید نشان دهد بازبین فقط مهر تأیید میزند.
در ابزارهای اتوماسیون گردش کار، وسوسه میشوید این موضوع را به یک نود تأیید محدود کنید. مقاومت کنید. گردش کار باید از ابتدا برای ثبت زمینه، توقف امن، تعیین مهلت، اطلاعرسانی متناسب، واگذاری جایگزین و ثبت نتیجه طراحی شود. ابزار فقط میتواند این منطق را اجرا کند؛ خودش منطق کنترل را اختراع نمیکند.
اگر میخواهید از همین هفته شروع کنید، یک جریان پرریسک اما محدود را بردارید. سه نوع تصمیم را تعریف کنید: خودکار، نیازمند بازبینی و ممنوع برای اجرای خودکار. برای دسته دوم، بسته تصمیم، زمان پاسخ، نقش جایگزین و گزینه اصلاح را مشخص کنید. سپس بعد از چند هفته، نه فقط خروجی AI، بلکه تصمیمهای انسانی روی آن خروجی را مرور کنید.
سیستم AI بالغ سیستمی نیست که کمتر از انسان سؤال میپرسد. سیستمی است که سؤال درست را، در لحظه درست، از آدم درست میپرسد؛ و از پاسخ او چیزی یاد میگیرد. دکمه تأیید شاید لازم باشد، اما کنترل از طراحی صف تصمیم شروع میشود، نه از فشردن آن دکمه.
Many AI workflows are designed around a misunderstanding: if we place an “approve” button at the end, a human is still in control. In practice, that button is often just the final stop in an ambiguous process, where a reviewer must sign off on a decision within seconds without seeing its context, understanding its consequences, or having time to examine it properly.
Human approval, by itself, is not control. Sometimes it is merely a transfer of responsibility. The system produces its recommendation, a tired or overloaded user approves it, and when something goes wrong, everyone says, “But a human approved it.” This model gives neither discipline to the AI nor real authority to the person.
Real control starts much earlier than the approval button: with the question of which decisions should reach a human at all. Not every output deserves human review. Send every case into a queue and the queue becomes crowded, attention disappears, and reviewers gradually learn to click “approve.” This is approval fatigue: a state in which too many repeated approval requests wear down a reviewer’s care and judgment, quietly eroding the quality of control.
At the other extreme, if nothing is escalated to a person, automation gains authority where it has not earned it. The issue is not choosing between total human control and total automation. The issue is designing the decision boundary so that the machine moves clear, low-risk, reversible work forward while humans own ambiguity, risk, and consequences that are hard to reverse.
Start with one real workflow, not an ideal diagram on a whiteboard. Suppose, for example, that AI is reviewing a proposed production schedule change, flagging a quality discrepancy, or recommending an action involving sensitive data. Then separate the decisions. “Analyzing data,” “recommending an action,” and “executing an action” are not the same decision, even when they sit next to one another in a single workflow.
At each stage, ask: what is lost if the system is wrong? Is the error reversible? Does it affect only internal work, or does it reach customers, quality, safety, contractual commitments, or sensitive data? Is the AI deciding with complete information, or facing incomplete and changing inputs? The answers should determine whether a case passes automatically, enters a review queue, or is blocked from the start.
An escalation threshold should not be based only on a confidence score. A model can be confidently wrong, especially when a case falls outside familiar data. A better threshold combines confidence, consequence severity, reversibility, data sensitivity, financial or operational value, and signs of unusual input. The more expensive or difficult a decision is to undo, the stronger the case for human review.
One simple rule is useful: AI can recommend, but when a decision is both ambiguous and costly, it should not execute alone. This rule is deliberately simple because its purpose is not to create a perfect risk model. Its purpose is to move the team beyond the vague idea that “a human should be in the loop” and explicitly define execution rights for each decision.
But a review queue is not just a place where work accumulates. The queue is an operational product. If a reviewer does not know why a case reached them, what options they have, and what their response will change, even the best escalation policy fails in execution. Someone who sees only a recommendation and two buttons will usually choose the fastest path, not the most responsible one.
Every item in the queue needs a decision package. It does not need to be long or theatrical, but it must make the issue judgeable: what the AI recommends, what evidence it relied on, what data was missing or contradictory, what the risk level is, what action is about to happen, and what happens if no action is taken. Reviewers should not have to wander across several systems to understand the context.
Design the options around the recommendation as real choices. Approve, reject, and edit are the minimum. Sometimes deferral, a request for more information, or escalation to another role is also necessary. More important than the number of buttons is their meaning. “Reject” must be able to stop the workflow; “edit” must record the human change; and “escalate” must have a next owner, a reason, and a follow-up time.
If rejecting a recommendation carries a high social or operational cost, reviewers will not reject it in practice. For example, when rejection means restarting a long process, or when nobody can see why a case was rejected, approval becomes the default choice. Good design should make responsible disagreement easier, not merely make approval easier.
This is where the right to challenge becomes meaningful. A challenge is not only for customers or managers. The reviewing specialist should be able to say that the evidence is insufficient, the issue has been classified incorrectly, the risk has been underestimated, or the case should never have entered this queue. That challenge should not disappear into scattered notes. It should be part of the workflow and feed back into redesigning the rule or the input data.
Time is also part of control. A queue without a response time either sits waiting or reaches rushed, careless approvals under last-minute pressure. Set an expected response time for each type of decision. Urgent cases need a clear and limited path; ordinary cases should not disturb everyone with repeated notifications for no reason. Permanent urgency is simply disorder at high volume.
Cases that receive no response within the defined time need an alternative path. But automatic escalation to a manager is not a universal answer. Managers often lack operational context and become bottlenecks. It is better to define an alternate role for each decision type: someone with authority, sound judgment, and an understanding of the responsibility that comes with accepting the decision.
In an industrial scenario, imagine that a system detects a product quality discrepancy and recommends holding a shipment. That decision should not reach the quality lead as nothing more than a “high confidence” label. They should see which data points conflict with the normal pattern, the likely scope of impact, which shipments or orders are involved, and whether alternatives such as resampling or limiting delivery are available.
If the quality lead edits the recommendation and chooses additional inspection instead of a full stop, that is not merely an exception. It is a valuable piece of data. The system should record what the AI proposed, what the human changed, why it was changed, and what the real outcome was. Without this decision trail, the organization only knows what was done; it does not know why the previous rule was insufficient for judgment.
This record is not for blaming reviewers. If decision logging becomes a tool for monitoring individuals, people will either write no explanation or write useless ones. The goal is operational learning: which thresholds are poorly set, which evidence is missing, which categories are escalated too often, and where either the AI or the human process needs improvement.
Do not measure the quality of human-AI collaboration by the number of approvals. Rejection or edit rates, handling time, the volume of stalled cases, repeat escalations, the percentage of reversed decisions, and patterns in challenges usually tell you more. A high rejection rate is not necessarily bad; it may show that the queue is correctly capturing complex cases. A near-zero rejection rate is not necessarily good; it may mean reviewers are simply rubber-stamping.
In workflow automation tools, you may be tempted to reduce this to a single approval node. Resist that temptation. The workflow should be designed from the start to capture context, stop safely, set deadlines, send proportionate notifications, assign an alternate owner, and record outcomes. The tool can execute this control logic; it cannot invent the logic for you.
If you want to begin this week, choose one high-risk but limited workflow. Define three types of decisions: automatic, review-required, and prohibited from automatic execution. For the second category, define the decision package, response time, alternate role, and editing option. Then, after a few weeks, review not only the AI outputs but also the human decisions made around those outputs.
A mature AI system is not one that asks humans fewer questions. It is one that asks the right question, at the right moment, of the right person, and learns something from the answer. An approval button may be necessary, but control begins with the design of the decision queue, not with pressing that button.
اگر این موضوع شبیه مسئله واقعی کسبوکار توست، از چکاپ تصمیم شروع کن.
یک مسیر کوتاه برای روشنکردن مسئله، گلوگاه تصمیم و قدم بعدی؛ بدون فرم طولانی و بدون تعهد.