Mem++: Non-Destructive Long-Term Memory for Organizational Agents
Mem++ preserves complete organizational documents with dates and authors, deferring the choice among conflicting versions until question answering.
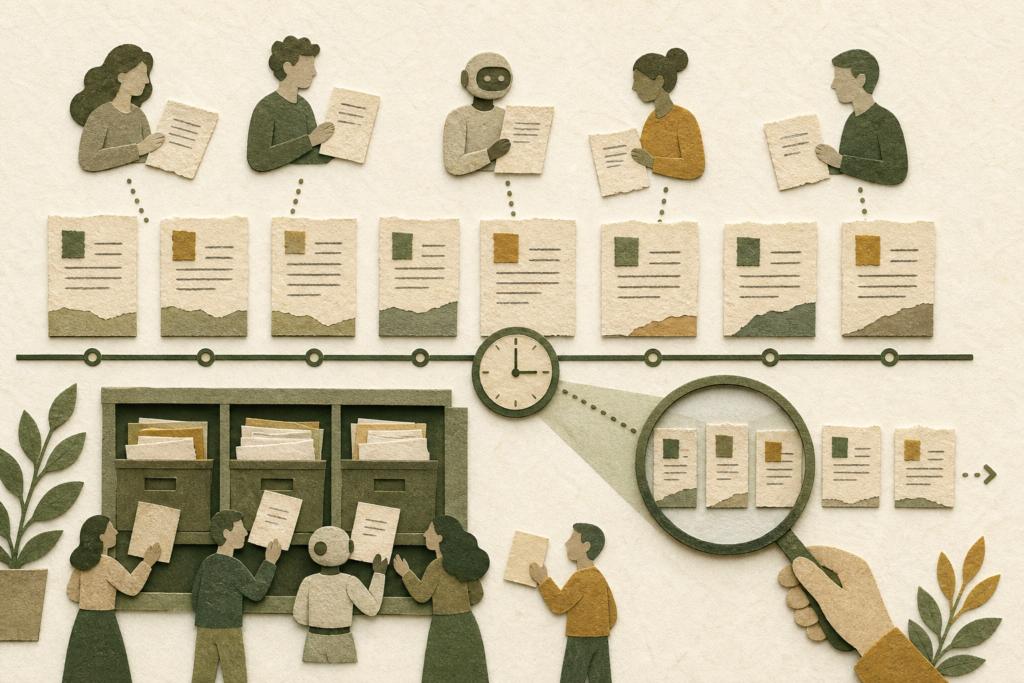
Table of contents
This overview relies on the available arXiv version of the paper, identifier 2610.02002, v1 dated October 1, 2026; this is a preprint, and its independent peer-review status is not confirmed. The paper examines memory for language-model agents in organizations, where decisions are recorded across emails, tickets, meeting notes, and documents by multiple authors over months. A changed decision usually creates a new document rather than editing the old one, so a correct answer can depend on the version valid at a particular date.
The authors present Mem++ as a “non-destructive” memory system. It stores each document in full, together with its text, author, event date, embedding, and state, and uses no generative model on the write path. Records are neither deleted nor rewritten; only their state can indicate that a later version superseded them. The goal is to preserve the ability to answer from the original text and all historical versions, unlike systems that extract facts or summaries at ingestion time.
At read time, Mem++ retrieves documents through lexical, author-tag, and semantic paths, then combines rankings with weighted reciprocal-rank fusion. When a question has an as-of date, only active records dated on or before that date enter all three paths. Of the 50 retrieved records used in the main experiments, three slots are reserved for remaining matches with the most recent event dates. The original text, date, and author where available are then passed to the answering model.
The primary evaluation uses the medium tier of OrgMemBench: 443 dated artifacts in 157 threads over 18 months, with 73 questions across six capabilities, including supersession, provenance, bi-temporal reasoning, and justification chains. The main metric is an LLM-judge score using gpt-4o-mini; on OrgMemBench, answers are assessed against 247 rubric facets. The conversational LoCoMo and LongMemEval_S datasets are also used. Comparisons include Full Context, RAG, Mem0, Zep, and, depending on the dataset, methods such as A-Mem, Nemori, and gbrain.
With gpt-4.1-mini, Mem++ obtained an overall OrgMemBench score of 57.6, 2.6 points above RAG and 13.1 points above the strongest compared memory system, A-Mem. With gpt-4o-mini, Mem++ scored 44.2 and its graph variant, Mem_g++, scored 44.4, versus 43.4 for RAG; Mem++ was 8.0 points above the best other memory system, Zep. Mem++ also reported the best average LLM-judge score on LoCoMo with both answer models, but ranked second to its graph variant on LongMemEval_S. In ablations, removing the semantic path caused large drops, including 35.7 points on OrgMemBench.
The limitations matter. The organizational evaluation rests on only 73 questions about one fictional organization; the paper does not report more diverse or real organizational records. In OrgMemBench, only 15 Audit Replay questions have an as-of date, and the answering model sees only the first 40,000 characters of context—about 19 of 50 retrieved rows—so recency-reserve rows and graph triples may not reach the model. Mem_g++ also uses undated triples, which can introduce information from after an as-of date. Its graph benefit was not consistent across answering models.
Explore more research
Read more AI research and analysis.
Related and recommended next reads
 PerMIT: Protecting Persistent Memory for LLM Agents with Content Confirmation and Community Trust
Recommended next · October 23, 2026
 Enterprise AI Assistant Compliance Under Pressure
Recommended next · October 13, 2026
 PACT: Testing Enterprise AI Agent Compliance Under Pressure
Recommended next · October 11, 2026