Controlling Errors in Multi-label Video Safety Detection with ATPO
This paper introduces ATPO, a method for making the precision–recall trade-off controllable in multi-label unsafe-video detection. Experiments on two benchmarks show that its adaptive reward outperforms static rewards, but these findings rely on a preprint whose independent peer review is unconfirmed, and selecting error ratios and validating under real policies and data remain necessary.
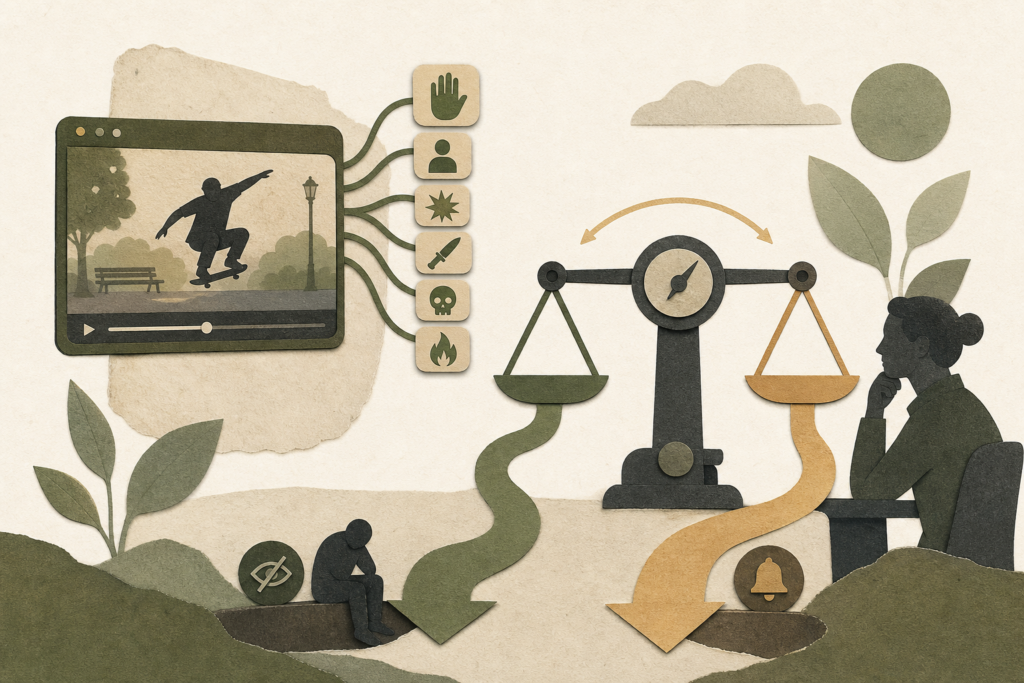
Table of contents
This introduction is based on the available arXiv:2610.02019v1 version; its independent peer-review status is not confirmed here. The paper extends video safety detection from binary “safe/unsafe” classification to multi-label detection: a video may simultaneously contain, for example, violence and illegal activity. The authors argue that moderation systems do not need one fixed operating point; some policies prioritize reducing missed harmful content, while others prioritize reducing incorrect flags.
The proposed Adaptive Tversky Policy Optimization, or ATPO, is a reinforcement-learning framework built on GRPO. Training first starts with one epoch of supervised fine-tuning on correct label sets, then continues with GRPO. Rewards are computed from true positives, false positives, and false negatives. The standard Tversky index uses fixed coefficients to penalize false positives and false negatives; increasing the false-positive penalty emphasizes precision, while increasing the false-negative penalty emphasizes recall.
The central contribution is the Adaptive Tversky Reward, or ATR. Using exponential moving averages of false-positive and false-negative errors, it measures the observed FN/FP ratio during training. A feedback controller then changes the Tversky coefficients to approach a user-specified target ratio. G-ATR uses one target ratio across all categories, whereas C-ATR assigns each category its own controller and target ratio. The aim is therefore to adjust training behavior, not merely to change a post-training threshold.
Experiments use SafeWatch-Bench and XD-Violence. Training uses 11,036 complete SafeWatch-Bench videos shorter than two minutes and 3,520 XD-Violence videos shorter than five minutes. Evaluation is conducted on 820 SafeWatch-Bench-Real videos and the 800-video XD-Violence test set, respectively, with Qwen2.5-VL-7B-Instruct and Qwen3-VL-8B-Instruct backbones. Metrics are Jaccard, Micro-F1, Macro-F1, and Binary F1. On SafeWatch-Bench-Real, Qwen2.5-VL-7B Jaccard rises from 40.66 zero-shot to 75.44 with ATPO-G; ATPO-C reaches 75.15.
A matched comparison from the one-epoch SFT initialization shows that ATPO-G raises Jaccard on SafeWatch-Bench-Real from 70.09 with static Tversky reward to 75.44; on the GenAI subset, it rises from 69.12 to 74.29. In global control, increasing the target ratio from 0.2 to 5 moves precision/recall from 0.77 to 1.16 and FN/FP from 0.31 to 1.75. In category-level control, misinformation precision changes from 55.28 to 70.41, while extreme-content recall changes from 79.07 to 94.57, accompanied by a drop in extreme-category precision from 80.31 to 31.77.
Important limitations remain. Evaluation relies only on existing benchmark definitions and annotations, while boundaries for violence, misinformation, or extremism may vary across cultures, laws, and platforms. Target ratios have no universal value and require data-based validation for each use case; unsuitable ratios can cause over-moderation or missed harmful content. The paper reports no confidence intervals or statistical-significance tests across repeated runs. Three RL epochs took about 20 hours on four 80GB NVIDIA H800 GPUs. The authors position the system as an assistive signal for human moderation, not an autonomous replacement for human judgment.
Explore more research
Read more AI research and analysis.
Related and recommended next reads
 Enterprise AI Assistant Compliance Under Pressure
Recommended next · October 13, 2026
 A Rubric Landscape for Evaluating Clinical Reasoning in Large Language Models
Recommended next · October 4, 2026
 Disentangling Spatial Reasoning Failures with Composable Video Operators
Recommended next · October 4, 2026