SIEVE: فراموشسازی انتخابی اطلاعات در مدلهای بینایی-زبان با سرکوب مقادیر توجه
روش SIEVE با سرکوب مقادیر توجه برای نمونههای فراموشی و تطبیق آنها با مدل مرجع برای نمونههای نگهداری، بازیابی پیوندهای حساس تصویر–پرسش–پاسخ را کاهش میدهد. نتایج گزارششده روی MLLMU-Bench، حفظ رقابتی دانش مجاز را نیز نشان میدهند.
فهرست مطالب
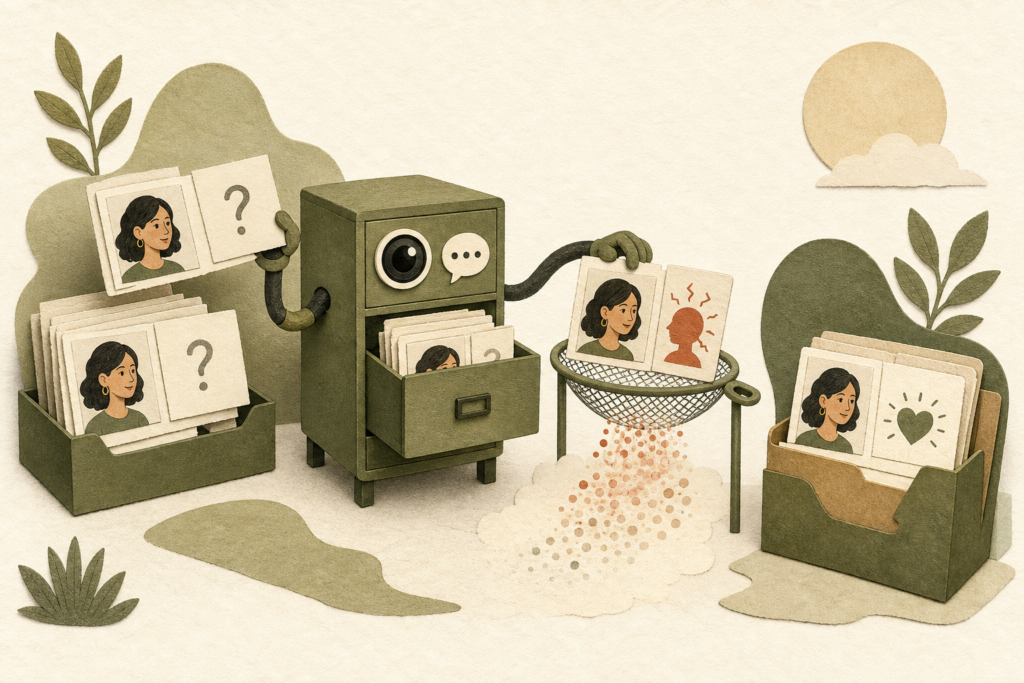
این معرفی بر پیشچاپ arXiv:2610.01962v1 تکیه دارد که در صفحه آن تاریخ اکتبر ۲۰۲۶ ذکر شده است. داوری همتای مستقل این اثر در اینجا تأیید نشده و مقاله ذکری از پذیرش در کنفرانس یا ژورنال نمیکند؛ بنابراین، نتایج و تفسیرهای زیر صرفاً ادعاهای نویسندگان در همین پیشچاپاند، نه یافتههای داوریشده. مقاله به «فراموشسازی انتخابی» در مدلهای بینایی-زبان میپردازد: حذف یک پیوند حساس میان تصویر، پرسش و پاسخ، بدون حذف اطلاعات مجاز درباره همان فرد. مثلاً تاریخ تولد باید فراموش شود، اما سرگرمی همان فرد باقی بماند، حتی وقتی هر دو پرسش به یک تصویر وابستهاند.
نویسندگان SIEVE را معرفی میکنند که بر بردارهای value در self-attention مداخله میکند. خروجی هر سر توجه از وزنهای توجه P و مقادیر V ساخته میشود. برای نمونههای فراموشی، روش مقدارهای V ثبتشده در لایههای انتخابی را به هدف صفر نزدیک میکند و همزمان cross-entropy توالی را بیشینه میسازد تا بازتولید پاسخ حساس دشوار شود. مقاله تأکید میکند که V لزوماً محل انحصاری ذخیره اطلاعات حساس نیست، بلکه نقطهای محاسباتی برای مداخله است.
برای نمونههای نگهداری، یک کپی ثابت از مدل پیش از فراموشسازی بهعنوان مرجع عمل میکند. مدل بهروزشده مقدارهای V خود را برای ورودیهای مجاز با مقدارهای مدل مرجع تطبیق میدهد و cross-entropy معمول پاسخهای مجاز را کمینه میکند. آموزش در هر epoch میان فازهای جداگانه فراموشی و نگهداری تناوب دارد. در پیکربندی گزارششده، فقط آداپتورهای LoRA روی همه projectionهای value دیکودر آموزش میبینند؛ رتبه و ضریب مقیاس ۱۶، dropout برابر ۰٫۰۵، چهار epoch و نرخ یادگیری ۲×۱۰⁻⁵ است.
آزمایشها روی MLLMU-Bench، شامل ۵۰۰ پروفایل ساختگی و ۱۵۳ پروفایل سلبریتی واقعی، با LLaVA-1.5-7B و Qwen2-VL-7B-Instruct انجام شدهاند. ارزیابی هم Visual-QA و هم Textual-QA را شامل میشود و از دقت طبقهبندی، دقت cloze و ROUGE-L تولید استفاده میکند. امتیاز کمتر در Forget و Test و بیشتر در Retain و Real مطلوب است. طبق جدول مقاله، SIEVE در هر چهار ترکیب مدل–حالت، کمترین امتیاز طبقهبندی و cloze مجموعه Forget را میان روشهای مقایسهشده دارد.
در LLaVA، SIEVE نسبت به قویترین مبنا بر معیار طبقهبندی Forget، کاهش بیشتری برابر ۱۶٫۵۳ واحد در Visual-QA و ۶٫۱۳ واحد در Textual-QA گزارش میکند؛ امتیازهای cloze متناظر به ۱۵٫۵۵ و ۵٫۶۶ میرسند. در Visual-QAِ LLaVA، طبقهبندی Forget از ۶۹٫۶۷ در مدل اولیه به ۲۰٫۰۶ کاهش یافت، در حالی که امتیازهای Retain برای طبقهبندی، تولید و cloze بهترتیب ۳۹٫۲۰، ۰٫۳۹۱ و ۲۷٫۹۵ بودند. حفظ کارایی در همه معیارها یکدست نیست؛ برای نمونه در برخی ترکیبها نمره Retain نسبت به مدل اولیه افت میکند، اما نویسندگان عملکرد کلی را رقابتی توصیف میکنند.
در مطالعه حذفی، حذف سرکوب value یا cross-entropy منفی، فراموشی را ضعیفتر کرد؛ حذف تطبیق با مدل مرجع امتیاز Forget را پایینتر آورد، اما افت چشمگیری در Retain ایجاد کرد. محدودیت مهم این است که ارزیابی به MLLMU-Bench، نسبتهای فراموشی ۵، ۱۰ و ۱۵ درصد، و مدلها و وظایف گزارششده محدود است؛ بنابراین این یافتهها تضمین حذف کامل اطلاعات شخصی در همه ورودیها یا مدلها نیستند. تحلیل ریاضی ضمیمه نیز فقط تغییر حالت پنهان را کرانبندی میکند و کرانی برای احتمال بازیابی پاسخ هدف ارائه نمیدهد.
This overview relies on preprint arXiv:2610.01962v1, whose listing page shows an October 2026 date. Its independent peer-review status has not been confirmed here, and the paper does not mention acceptance at any venue; the results and interpretations below are therefore the authors’ claims in this preprint, not peer-reviewed findings. The paper addresses "selective unlearning" in vision-language models: removing a sensitive image–question–answer association without removing permitted information about the same person. For instance, a date of birth should be forgotten while the person’s hobby remains available, even when both questions use the same image.
The authors introduce SIEVE, which intervenes on value vectors in self-attention. Each attention-head output is formed from attention weights P and values V. For forget examples, the method pushes recorded V values in selected layers toward a zero target while maximizing sequence cross-entropy, making reproduction of the sensitive answer harder. The paper stresses that V is not necessarily the exclusive storage location of sensitive information; it is treated as a computational intervention point.
For retain examples, a frozen copy of the pre-unlearning model serves as the reference. The updated model matches its V values for permitted inputs to the reference values and minimizes ordinary cross-entropy on permitted answers. Training alternates between separate forget and retain phases within each epoch. In the reported configuration, only LoRA adapters on all decoder value projections are trained; rank and scaling are 16, dropout is 0.05, training runs for four epochs, and the learning rate is 2×10⁻⁵.
Experiments use MLLMU-Bench, containing 500 fictitious profiles and 153 real-celebrity profiles, with LLaVA-1.5-7B and Qwen2-VL-7B-Instruct. Evaluation covers both Visual-QA and Textual-QA and uses classification accuracy, cloze accuracy, and generation ROUGE-L. Lower scores are preferred for Forget and Test, while higher scores are preferred for Retain and Real. According to the paper’s table, SIEVE has the lowest Forget-set classification and cloze scores among compared methods in all four model–modality combinations.
On LLaVA, SIEVE reports an additional 16.53-point reduction in Forget classification in Visual-QA and 6.13 points in Textual-QA relative to the strongest baseline on that metric; corresponding cloze scores reach 15.55 and 5.66. In LLaVA Visual-QA, Forget classification falls from 69.67 in the initial model to 20.06, while Retain classification, generation, and cloze scores are 39.20, 0.391, and 27.95. Utility preservation is not uniform across metrics; some settings show Retain scores below the initial model, but the authors describe overall performance as competitive.
In ablations, removing value suppression or negative cross-entropy weakened forgetting; removing reference matching further lowered Forget scores but caused substantial degradation in Retain performance. An important limitation is that evaluation is restricted to MLLMU-Bench, forget ratios of 5%, 10%, and 15%, and the reported models and tasks. These findings therefore do not guarantee complete removal of personal information across all inputs or models. The appended mathematical analysis bounds hidden-state change only and provides no bound on the probability of recovering a target answer.
پژوهشهای بیشتری بخوان
مقالات بیشتر درباره هوش مصنوعی و پژوهشهای تازه را ببین.