همبستگی جهانی در همکاری چندعامله
این مقاله مسئلهای را بررسی میکند که در آن هر عامل بر پایه دید محلی خود درست عمل میکند، اما نتیجه ترکیبی تیم با قیدهای مشترک ناسازگار میشود. پیشنهاد اصلی، واگذاری مالکیت وضعیت و کنترل تعهدها به یک مهار بیرونی است.
فهرست مطالب
این معرفی بر نسخه پیشچاپ موجود در arXiv، یعنی arXiv:2610.02036v1 مورخ ۱ اکتبر ۲۰۲۶ تکیه دارد؛ این اثر هنوز داوری همتراز مستقل نشده و ادعاهای آن باید با همین وضعیت خوانده شوند. مقاله مسئله «همبستگی جهانی» را برای همکاری عاملهای هوش مصنوعی صورتبندی میکند: ممکن است هر عامل با توجه به زمینه محلی خود تصمیمی معتبر بگیرد، اما خروجی ترکیبی تیم نادرست باشد. نویسنده این مسئله را فقط ضعف مدل نمیداند، بلکه آن را مسئله وضعیت مشترک، مشاهده و تعهد تغییرها معرفی میکند.
نخستین نتیجه، «قضیه ناممکنی همنامی مشاهده» است. طبق آن، یک سیاست تنها وقتی از روی مشاهده خود میتواند همواره عملی معتبر انتخاب کند که همه جهانهای سازگار با آن مشاهده، دستکم یک عمل مجاز مشترک داشته باشند. اگر k وضعیتِ قابلتشخیصنبودن، عملهای مجازِ جدا از هم بخواهند، بهترین سیاست تصادفی در بدترین حالت دقیقاً احتمال موفقیت ۱/k دارد؛ راهنمای b بیتی نیز این مقدار را حداکثر به ۱/⌈k/2^b⌉ میرساند. یافتن کوچکترین مجموعه اطلاعات لازم برای اعتبارسنجی دقیق نیز NP-hard گزارش شده است.
شکست دوم حتی با وجود اطلاعات محلی درست رخ میدهد: قطعاتی که بهصورت دوتایی سازگارند، ممکن است به یک وضعیت جهانی واحد نچسبند. مقاله میگوید بررسیهای دوتایی در ساختارهای درختیِ همپوشانی کافیاند، اما چرخهها میتوانند ناسازگاری را پنهان کنند و هیچ کران ثابت محلی برای همه معناشناسیهای قیدی وجود ندارد. برای ترجمههای برگشتپذیر میان نمایشها، سازگاری حلقهها با یک جنگل پوشا در زمان خطی قابل تأیید است؛ ولی یافتن کمهزینهترین ترمیم ناسازگاری NP-hard است.
چارچوب پیشنهادی X=(H,C,G,F;D) پنج جزء دارد: H برای محل تلاقی و وابستگیها، C برای تغییرهای واقعی وضعیت، G برای ترجمههای هممعنا، F برای بررسی چسبیدن دیدهای محلی به یک جهان، و D برای تاریخچهای که بر مجازبودن آینده اثر دارد. در این معماری، مدلها پیشنهاد میدهند، اما «مهار همبستگی» وضعیت معنایی لازم را نگه میدارد، پیشنهادها را بررسی میکند و فقط تغییرهای پذیرفتهشده را تعهد میکند. نسخهگذاری، دفتر بودجه، موتور وابستگی و سهمیههای امانی نمونههای تخصصی همین نقشاند.
شواهد مقاله شامل نه مطالعه با یک خانواده مدل است. در آزمون ۴۰ مسئلهای بازبینی، مدل با مشاهده رخداد تعیینکننده ۴۰/۴۰ پاسخ درست داد؛ با پنهانشدن آن، بازوهای آزمودهشده ۱۲ تا ۱۷ پاسخ درست از ۴۰ داشتند و افزودن یک جمله حاوی واقعیت لازم دوباره ۴۰/۴۰ شد. در TeamBench، تیمهای عادی در ۵/۵ اجرا از بودجه مشترک ۲۰ فراخوان عبور کردند؛ نمایش شمارنده زنده ۴/۵ تخلف باقی گذاشت، اما اعمال محدودیت هنگام تعهد و سهمیهبندی امانی هر دو به ۰/۵ رسیدند. در τ²-bench Telecom نیز مهار پیشنهادی در تغییرهای بازگرداندهشده پنهانی امتیاز ۱٫۰۰ گرفت، در برابر ۰٫۰۷ برای بررسیهای متعارف.
محدودیتها مهماند: آزمایشهای عاملی بر یک خانواده مدل و پنلهای کوچک تکیه دارند، آزمون همنامی عمداً مصنوعی است و برخی خطاها در τ²-bench تزریق شدهاند؛ بنابراین مقاله نرخ طبیعی یا سهم این شکستها در همه بنچمارکها را برآورد نمیکند. همچنین حذف همه تعارضهای شبکهای در مطالعه همترازی با افت میانگین F1 از ۰٫۷۹۶ به ۰٫۷۷۴ همراه بود، پس تشخیص موفق الزاماً به معنای ترمیم باکیفیت نیست. نتیجه آزمودهشده محدودتر است: وقتی وضعیت تعیینکننده غایب یا بیمالک بوده، مهارِ مالک آن خطاهای هدف را در این پنلها کاهش داده یا حذف کرده است.
This introduction relies on the available arXiv preprint, arXiv:2610.02036v1 dated October 1, 2026; the work has not undergone independent peer review, and its claims should be read with that status in mind. The paper formulates “global coherence” as a multi-agent AI problem: each agent may make a valid decision from its local context while the team’s combined output is wrong. The author treats this not only as a model weakness, but as a problem of shared state, observation, and committing changes.
The first result is the “Observation-Aliasing Impossibility Theorem.” A policy can always choose a valid action from its observation only when every world compatible with that observation shares at least one admissible action. If k indistinguishable states require disjoint admissible actions, the best randomized policy has worst-case success exactly 1/k; a b-bit hint raises this to at most 1/⌈k/2^b⌉. Finding the smallest information set needed for exact validation is also reported as NP-hard.
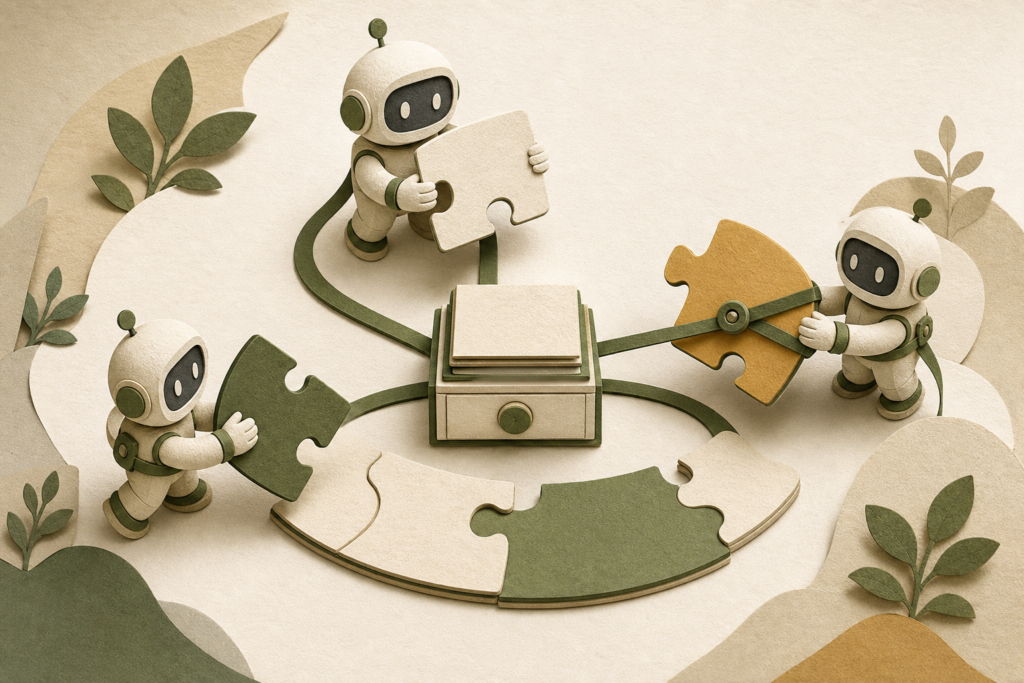
The second failure remains possible even when local information is correct: pieces that are pairwise compatible may fail to glue into one global state. The paper states that pairwise checks suffice for tree-shaped overlap structures, whereas cycles can hide inconsistency, and no fixed local bound works for all constraint semantics. For reversible translations between representations, loop consistency can be verified in linear time with a spanning forest; finding a minimum-cost repair of inconsistency is NP-hard.
The proposed framework, X=(H,C,G,F;D), has five components: H for where dependencies and overlaps meet, C for genuine state changes, G for meaning-preserving translations, F for checking whether local views glue into one world, and D for history that affects future admissibility. In this architecture, models make proposals, while a “coherence harness” retains the needed semantic state, checks proposals, and commits only accepted changes. Version checks, budget ledgers, dependency engines, and escrow quotas are specialized instances of this role.
The paper presents nine studies using one model family. In a 40-task revision test, the model answered 40/40 correctly when it saw the deciding event; when that event was hidden, tested arms produced 12 to 17 correct answers out of 40, while one sentence containing the required fact restored 40/40. In TeamBench, ordinary teams exceeded a shared 20-call budget in 5/5 runs; showing a live counter still left 4/5 violations, while commit-time enforcement and escrow quotas both reached 0/5. In τ²-bench Telecom, the proposed harness scored 1.00 on silently reverted changes, versus 0.07 for conventional checks.
The limitations matter: agent experiments rely on one model family and modest panels, the aliasing probe is deliberately synthetic, and some τ²-bench failures were injected. The paper therefore does not estimate the natural rate or overall contribution of these failures across benchmarks. Further, removing all network conflicts in the alignment study reduced mean F1 from 0.796 to 0.774, so successful detection does not itself imply high-quality repair. The tested conclusion is narrower: when deciding state was absent or unowned, a harness that owned it reduced or removed targeted failures in these panels.
پژوهشهای بیشتری بخوان
مقالات بیشتر درباره هوش مصنوعی و پژوهشهای تازه را ببین.