A Four-Axis Taxonomy for RAG Systems
This survey organizes RAG research around efficiency, defense, interactivity, and complex reasoning, while highlighting their shared limitations.
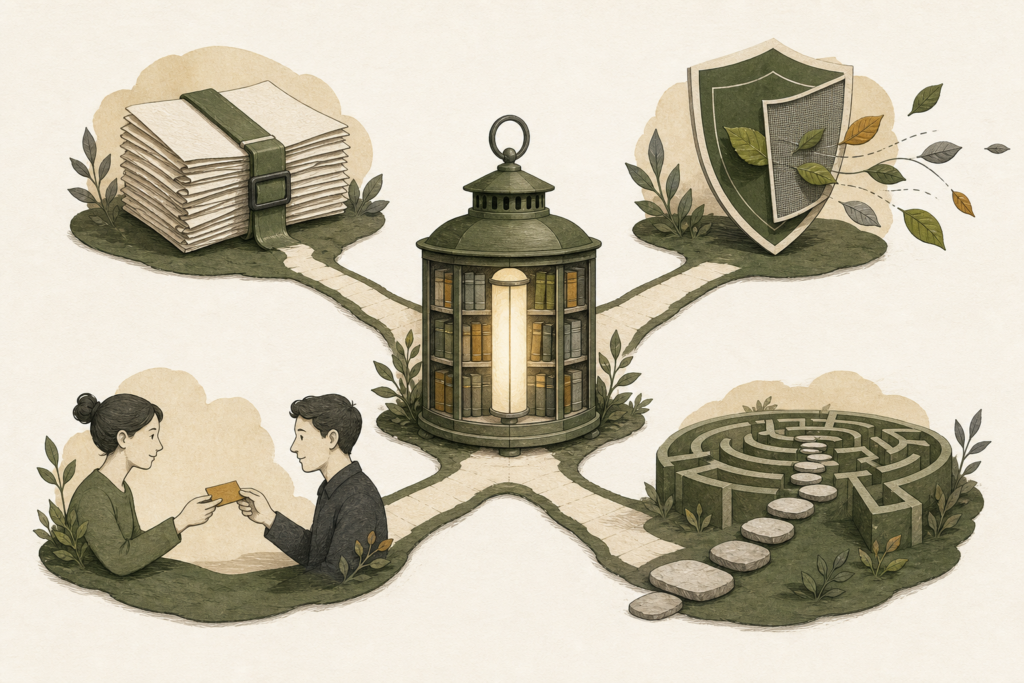
Table of contents
This overview is based on arXiv preprint 2610.01936, uploaded on 1 October 2026. The paper surveys Retrieval-Augmented Generation, or RAG: systems that use externally retrieved documents alongside a language model when answering. Its text does not mention peer review or acceptance at a journal or conference; that absence alone does not show the content is unreliable, but it does not permit describing the work as peer-reviewed. The independent peer-review status of this preprint remains unconfirmed.
The paper’s central finding is a four-axis organization of RAG literature: compression and efficiency, defensive RAG, user-centric interactivity, and complex multi-step reasoning. The authors do not treat RAG as a uniform pipeline, but as a set of design trade-offs: accuracy versus computational cost; countering corpus poisoning, amplified demographic bias, and privacy leakage; adapting to user intent and interaction history; and stepwise retrieval to reduce error accumulation in multi-hop tasks.
The review searched Google Scholar, Semantic Scholar, and arXiv from January 2020 through January 2025, identifying approximately 780 records at the initial stage through broad and targeted keywords. Included works needed an integrated retrieval-generation pipeline, methodological or empirical innovation, RAG-specific benchmarking, or study of security, robustness, fairness, or safety. Works without retrieval, standalone models or retrievers without integration, and papers without technical or empirical contribution were excluded. Citation tracing was a targeted completeness check rather than a repetition of the full search.
In the baseline formulation, corpus documents are chunked, embedded, and indexed; then top-ranked chunks are supplied with the query to the generator. Sparse retrieval such as BM25 relies on lexical overlap, while dense retrieval such as DPR relies on semantic matching in embedding space. The paper stresses that softmax weighting over retrieved documents is not universal: it operates only over the top-ranked set, inherits upstream retrieval errors, and assumes conditional independence among documents. Other systems use fixed top-k concatenation, reranking, or critique scores.
On the efficiency axis, the goal is maximizing each document’s utility relative to token cost; query refinement, hierarchical retrieval such as RAPTOR, and extreme context compression such as xRAG are examples. On the defensive axis, toxic, biased, or sensitive documents are filtered, reranked, or verified, as in SELF-RAG and FILCO; corpus poisoning risk and privacy leakage are also considered. Interactivity conditions document selection on query relevance, user history, and feedback. Complex reasoning repeats retrieval at each step so fresh evidence can correct or complete intermediate conclusions.
The paper states that retrieval quality and scalability, residual hallucination, domain and user adaptation, deployment latency, and missing end-to-end explainability remain unresolved. Personalization can conflict with factual accuracy, and in multi-step reasoning, early errors or poor question decomposition can accumulate into the final answer. The authors argue that one metric cannot assess all four axes, because cost and latency, adversarial robustness, user satisfaction, and multi-hop correctness rest on different measurement foundations; they instead propose a shared framework with axis-specific tracks. Reported numerical results are drawn from prior work.
Explore more research
Read more AI research and analysis.