SIEVE: Selective Unlearning in Vision-Language Models via Attention-Value Suppression
SIEVE suppresses attention values for forget examples and matches them to a reference model for retain examples, reducing recovery of sensitive image–question–answer associations. Reported MLLMU-Bench results also show competitive preservation of permitted knowledge.
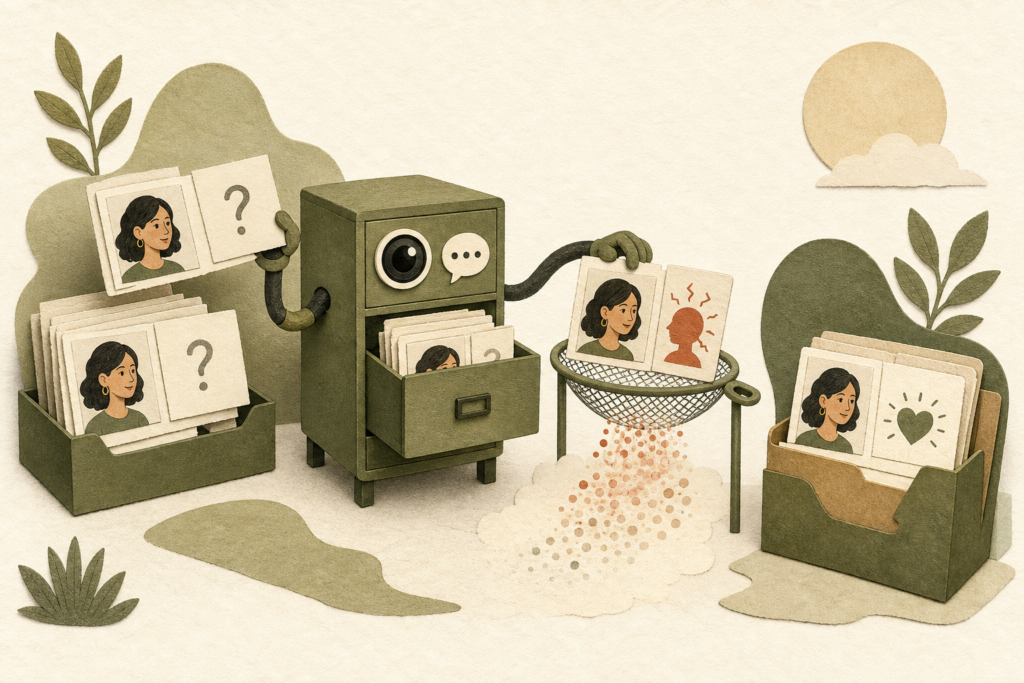
Table of contents
This overview relies on preprint arXiv:2610.01962v1, whose listing page shows an October 2026 date. Its independent peer-review status has not been confirmed here, and the paper does not mention acceptance at any venue; the results and interpretations below are therefore the authors’ claims in this preprint, not peer-reviewed findings. The paper addresses "selective unlearning" in vision-language models: removing a sensitive image–question–answer association without removing permitted information about the same person. For instance, a date of birth should be forgotten while the person’s hobby remains available, even when both questions use the same image.
The authors introduce SIEVE, which intervenes on value vectors in self-attention. Each attention-head output is formed from attention weights P and values V. For forget examples, the method pushes recorded V values in selected layers toward a zero target while maximizing sequence cross-entropy, making reproduction of the sensitive answer harder. The paper stresses that V is not necessarily the exclusive storage location of sensitive information; it is treated as a computational intervention point.
For retain examples, a frozen copy of the pre-unlearning model serves as the reference. The updated model matches its V values for permitted inputs to the reference values and minimizes ordinary cross-entropy on permitted answers. Training alternates between separate forget and retain phases within each epoch. In the reported configuration, only LoRA adapters on all decoder value projections are trained; rank and scaling are 16, dropout is 0.05, training runs for four epochs, and the learning rate is 2×10⁻⁵.
Experiments use MLLMU-Bench, containing 500 fictitious profiles and 153 real-celebrity profiles, with LLaVA-1.5-7B and Qwen2-VL-7B-Instruct. Evaluation covers both Visual-QA and Textual-QA and uses classification accuracy, cloze accuracy, and generation ROUGE-L. Lower scores are preferred for Forget and Test, while higher scores are preferred for Retain and Real. According to the paper’s table, SIEVE has the lowest Forget-set classification and cloze scores among compared methods in all four model–modality combinations.
On LLaVA, SIEVE reports an additional 16.53-point reduction in Forget classification in Visual-QA and 6.13 points in Textual-QA relative to the strongest baseline on that metric; corresponding cloze scores reach 15.55 and 5.66. In LLaVA Visual-QA, Forget classification falls from 69.67 in the initial model to 20.06, while Retain classification, generation, and cloze scores are 39.20, 0.391, and 27.95. Utility preservation is not uniform across metrics; some settings show Retain scores below the initial model, but the authors describe overall performance as competitive.
In ablations, removing value suppression or negative cross-entropy weakened forgetting; removing reference matching further lowered Forget scores but caused substantial degradation in Retain performance. An important limitation is that evaluation is restricted to MLLMU-Bench, forget ratios of 5%, 10%, and 15%, and the reported models and tasks. These findings therefore do not guarantee complete removal of personal information across all inputs or models. The appended mathematical analysis bounds hidden-state change only and provides no bound on the probability of recovering a target answer.
Explore more research
Read more AI research and analysis.