Turning 2D Vision-Language Models into 3D Programmers with Iterative Feedback
3D-Prog proposes using 2D vision-language models for 3D tasks without retraining through coordinate framing and execution feedback; this is a preprint with unverified independent review, and runtime cost, dependence on the base model, and automated-judging errors remain limitations.
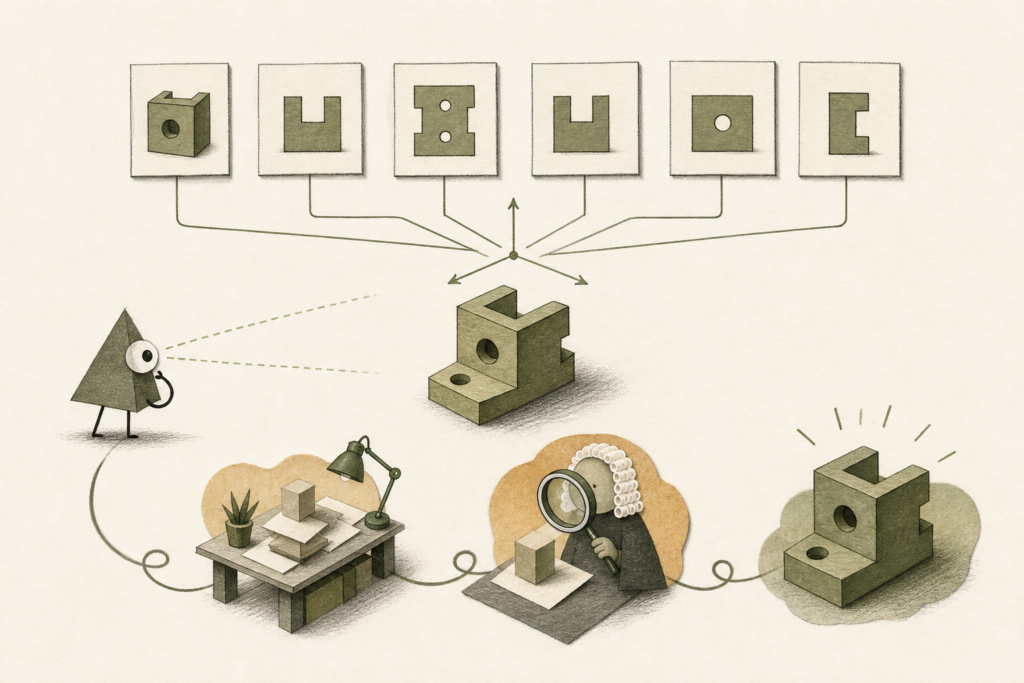
Table of contents
This overview relies on the October 2026 arXiv preprint of “Task-Adaptive Grounded 3D-Programmers Using 2D VLMs.” The paper does not mention acceptance or independent peer review; the absence of such a mention is not itself evidence that review occurred, so its independent-review status is unverified. The central problem is that 2D vision-language models are strong at semantics but struggle to maintain coordinates, scale, orientation, and part relationships in 3D. Rather than naively extending these models into 3D, the authors propose 3D-Prog to turn a 2D VLM, a 3D asset, and a language instruction into an executable USD program.
The first component is Canonical Coordinate Framing, or CCF. An input asset is rendered as six orthographic views plus one perspective view; every view includes a fixed origin, labeled X/Y/Z axes, and metric scale marks. The goal is reasoning within a shared Euclidean frame rather than guessing from a single image. The paper reports that removing visible axes causes orientation ambiguity, removing scale markings causes inconsistent scale, relying on perspective-only projections causes metric distortion, and purely parametric outputs cause a floating reference frame.
The second component, Task-Adaptive Feedback or TAF, is a loop between the model and a Python execution environment. The VLM generates USD-manipulation code and task-specific analysis code; this analysis can produce density heatmaps, height distributions, segmentation overlays, or DBSCAN clustering. These outputs are returned to the model alongside updated CCF views. A separate judge VLM then reports a completion status, confidence score, and diagnostic feedback (errors and suggestions) based on the instruction, visual comparison, and TAF analyses. The loop continues until judge approval or a cap of 20 iterations.
Experiments evaluate 3D generation, understanding, and reasoning on synthetic data and real-world scans at object and scene scales. Metrics include Chamfer distance, mAP, mIoU, motion-axis error, and two user studies with four evaluators; each reported result averages five assets. With a Claude backbone, 3D-Prog reports 0.19 Chamfer distance for object completion, 0.38 detection mAP, and 0.42 instance-segmentation mAP. The Kimi-backed version reports a 0.64-degree median articulation-axis error. In Scan2Sim, baseline models produced no valid USD outputs, while 3D-Prog with Claude and Kimi backbones reported Chamfer values of 0.08 and 0.09, respectively.
Ablations support the complementary roles of CCF and TAF: removing CCF dropped detection mAP from 0.38 to 0.01 and worsened completion Chamfer from 0.19 to 0.33; removing TAF worsened completion Chamfer to 0.58. In a translation-and-rotation robustness test on one object-completion asset, the method held 0.02 Chamfer under the reported translations and a 15-degree rotation, but its degradation at 45 degrees approached that of the baseline. Against GaussianVLM, SQA3D accuracy rose from 50% to 60% and Nr3D METEOR rose from 0.22 to 0.23. These are results from this paper’s specific experimental setup, not a universal conclusion across all models or scenes.
The limitations are material. Performance depends on the capability of the underlying VLM, and fine-grained detail or very complex reasoning remains difficult. The judge module assesses convergence rather than guaranteed correctness, so it may occasionally accept suboptimal results. The supplementary case study shows a semantic-labeling error that persisted despite geometrically correct segmentation. Additionally, the VLM’s visual context limits the scene size and detail that CCF can process. Average runtime was 11.4 iterations and 256 seconds on an RTX 5090 GPU with 32 GB memory; "without retraining" therefore does not mean without computational cost.
Explore more research
Read more AI research and analysis.