Global Coherence in Multi-Agent Collaboration
This paper studies cases where each agent acts correctly from its local view, yet the team’s combined result violates shared constraints. Its central proposal is an external harness that owns relevant state and governs commits.
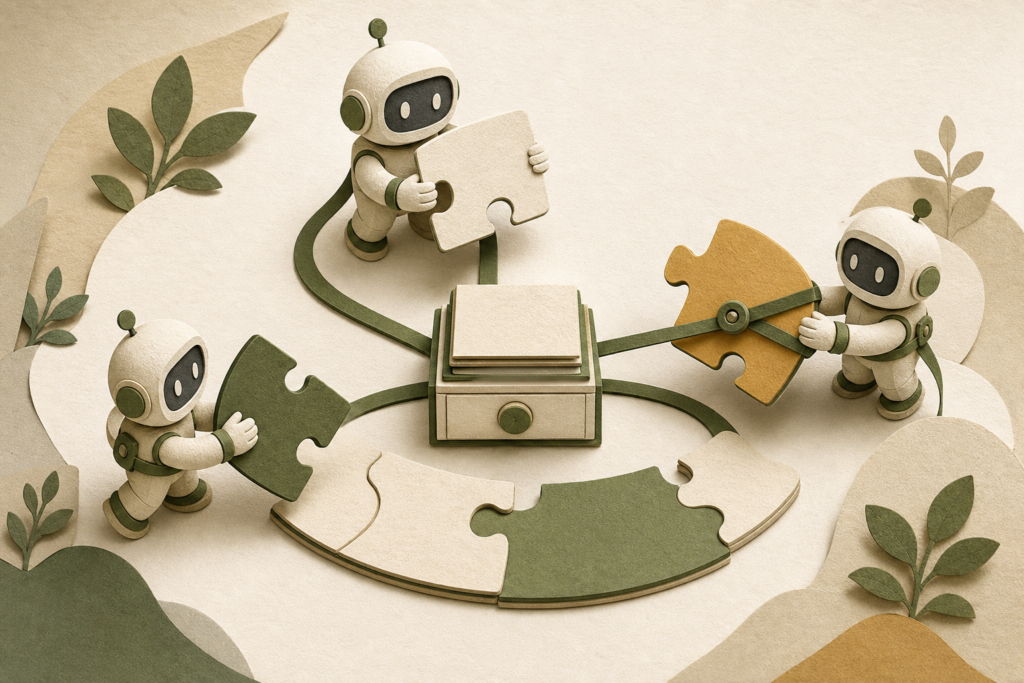
Table of contents
This introduction relies on the available arXiv preprint, arXiv:2610.02036v1 dated October 1, 2026; the work has not undergone independent peer review, and its claims should be read with that status in mind. The paper formulates “global coherence” as a multi-agent AI problem: each agent may make a valid decision from its local context while the team’s combined output is wrong. The author treats this not only as a model weakness, but as a problem of shared state, observation, and committing changes.
The first result is the “Observation-Aliasing Impossibility Theorem.” A policy can always choose a valid action from its observation only when every world compatible with that observation shares at least one admissible action. If k indistinguishable states require disjoint admissible actions, the best randomized policy has worst-case success exactly 1/k; a b-bit hint raises this to at most 1/⌈k/2^b⌉. Finding the smallest information set needed for exact validation is also reported as NP-hard.
The second failure remains possible even when local information is correct: pieces that are pairwise compatible may fail to glue into one global state. The paper states that pairwise checks suffice for tree-shaped overlap structures, whereas cycles can hide inconsistency, and no fixed local bound works for all constraint semantics. For reversible translations between representations, loop consistency can be verified in linear time with a spanning forest; finding a minimum-cost repair of inconsistency is NP-hard.
The proposed framework, X=(H,C,G,F;D), has five components: H for where dependencies and overlaps meet, C for genuine state changes, G for meaning-preserving translations, F for checking whether local views glue into one world, and D for history that affects future admissibility. In this architecture, models make proposals, while a “coherence harness” retains the needed semantic state, checks proposals, and commits only accepted changes. Version checks, budget ledgers, dependency engines, and escrow quotas are specialized instances of this role.
The paper presents nine studies using one model family. In a 40-task revision test, the model answered 40/40 correctly when it saw the deciding event; when that event was hidden, tested arms produced 12 to 17 correct answers out of 40, while one sentence containing the required fact restored 40/40. In TeamBench, ordinary teams exceeded a shared 20-call budget in 5/5 runs; showing a live counter still left 4/5 violations, while commit-time enforcement and escrow quotas both reached 0/5. In τ²-bench Telecom, the proposed harness scored 1.00 on silently reverted changes, versus 0.07 for conventional checks.
The limitations matter: agent experiments rely on one model family and modest panels, the aliasing probe is deliberately synthetic, and some τ²-bench failures were injected. The paper therefore does not estimate the natural rate or overall contribution of these failures across benchmarks. Further, removing all network conflicts in the alignment study reduced mean F1 from 0.796 to 0.774, so successful detection does not itself imply high-quality repair. The tested conclusion is narrower: when deciding state was absent or unowned, a harness that owned it reduced or removed targeted failures in these panels.
Explore more research
Read more AI research and analysis.
Related and recommended next reads
 PerMIT: Protecting Persistent Memory for LLM Agents with Content Confirmation and Community Trust
Recommended next · October 23, 2026
 Enterprise AI Assistant Compliance Under Pressure
Recommended next · October 13, 2026
 PACT: Testing Enterprise AI Agent Compliance Under Pressure
Recommended next · October 11, 2026