HydroJEV: Fast Screening for Attribution of Water-Network Anomalies
A preprint tests the training-free Jev screen for attributing SCADA alarms in water networks; its independent peer-review status is unconfirmed.
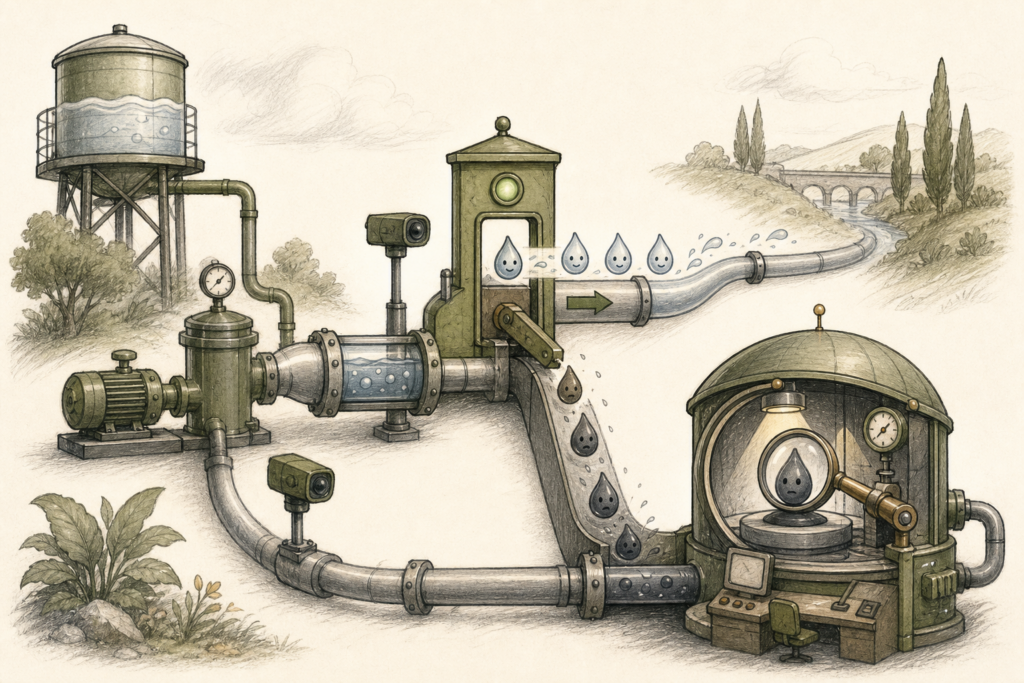
Table of contents
This introduction is based on an arXiv preprint (version 1, dated 1 October 2026) whose independent peer-review status is not stated in the text and is not treated as peer-reviewed in this introduction. HydroJEV examines the question that follows a SCADA alarm in a water distribution network: does an anomaly stem from a cyberattack, a physical fault, a normal transient, or a sensor fault? The authors present Jev as a training-free screen that returns probabilities over fixed options in about a second and sends unresolved cases to slower review.
The main experiment used the simulated C-Town network in EPANET. Each sample was a six-hour SCADA window from hourly simulations and belonged to one of four classes. The data contained a reference family and three unseen event families; family C included look-alike events, such as a real pump trip versus a spoofed stop. In total, 1,279 windows were evaluated in four sealed, preregistered rounds, and each test set was analysed only once.
All methods received the same evidence: control settings, measurement-consistency checks, the ten largest digital-twin residuals, a signed summary, and source-flow balance. Jev used a fixed five-option question that included “insufficient evidence.” Its output was adjusted using a label-free prior correction estimated from 40 development windows. Comparisons included the hand-written R1 rule tree, supervised logistic-regression model R2 with 200 labelled samples, and seven cloud LLMs.
Across four in-distribution sets, calibrated Jev achieved macro-F1 from 0.620 to 0.644, averaging 0.63; R1 averaged 0.59, and individual-set differences were not significant. R2 performed better when trained on labels covering all similar subtypes, averaging 0.91. However, when the evaluated subtype was removed from R2 training, Jev was ahead by 0.361 to 0.417 macro-F1 points in all four rounds; every test remained significant after Holm correction. On in-distribution data, R2 surpassed Jev on average from about four labelled examples per class onward.
Jev’s median compute time was about 1.22 seconds; glm-5.2 and deepseek-v4-pro were roughly 20 to 40 times slower when requests were sent one at a time. Two frontier LLMs were more accurate on some sets. In the proposed cascade, only a benign Jev verdict also confirmed by R1 was accepted, while other windows went to an LLM reviewer. On the two fresh round-4 sets, the gate accepted 34.5% and 38.0% of windows, and the glm-5.2 cascade stayed within the 0.03 non-inferiority margin of its reviewer without loss of macro-F1.
The limitations are substantial. All windows were simulated, and the same hydraulic model generated both events and the digital twin; thus model error in field data is not fully represented. Jev was weaker on concealed manipulation, with mean cyberattack recall of 0.34 across eight C-Town sets. In the unseen round-4 family, the agreement gate accepted some attacks and faults as benign; the rule cascade without the agreement gate also did not outperform its own components on fresh sets. The authors stress validation on simulated events and then field data from each network before practical use.
Explore more research
Read more AI research and analysis.