Argo-Bench: Evaluating Data Agents in Enterprise Workflows
Argo-Bench is a simulated environment for evaluating data agents that must navigate a large ERP warehouse, perform analysis, and submit results as actions or reports.
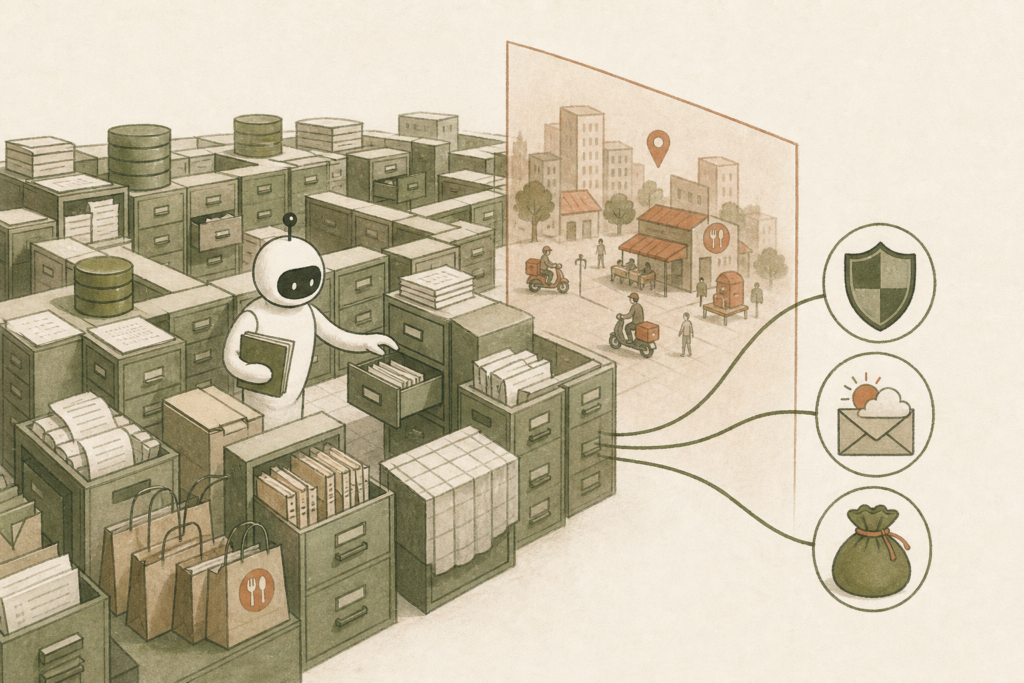
Table of contents
This paper, whose main subject is data agents, is an arXiv preprint dated October 1, 2026 and is described as “under review.” Its independent peer-review status has not been confirmed. The authors evaluate agents that go beyond generating SQL: they explore and interpret dispersed enterprise data, perform analysis, and convert results into actions or filed outputs. The paper’s focus is therefore AI-agent evaluation for data work.
Argo-Bench simulates a New York City food-delivery platform in 2024 and exports it to an Oracle E-Business Suite 12.2 warehouse. The evaluation warehouse has 235 tables and 7.49 billion rows, while the simulated world contains 81 million orders and 3.4 million active customers. Agents cannot access the simulator’s latent state, so they must reconstruct facts from tables, accounting relationships, and operational records. The latent state is used only for grading.
The benchmark contains 210 tasks in five areas: trust and safety, financial planning and analysis, marketplace, accounting, and growth. Tasks include banning fraudulent accounts, forecasting payments, allocating courier-incentive budgets, reporting financial figures, and publishing dashboard data. Agents have read-only SQL, a persistent Python environment, and statistics, machine-learning, and optimization libraries, but no outbound internet access. Outputs are filed through the Mission Control interface.
The grading method is based on the consequences of an agent’s filings rather than only matching a textual answer or gold query. Forecasts are evaluated against hidden months using weighted interval scores. Ban lists are scored using prevented fraud losses, review costs, and losses from incorrect bans, while budget plans are assessed in the simulator’s response model. The paper states that every task has an executable reference solution demonstrating solvability from the warehouse alone.
The authors evaluate 14 frontier and open-weight models. In the reported settings, Claude Opus 5.5 obtains the best result, with a mean score of 59.5 out of 100 and a 34.8% solved rate for tasks scoring at least 95. GPT-6 Astra is reported to lead forecasting, and Claude Sonnet 5.5 leads compliance. Failures are often attributed to selecting the wrong record, quantity, or objective. Across 4,553 series, nominal 80% intervals covered realized values only 44.8% of the time.
The limitations are consequential for interpretation. The world covers only one city, one year, and one ERP format; it lacks foreign currencies, combined multi-business operations, and the common inconsistencies of real warehouses. The simulator is validated on 23 metrics, but the membership program relies on more weakly grounded assumptions. Each model setting is run once per task and all tasks come from one world, so the paper does not estimate agent performance in a real company warehouse.
Explore more research
Read more AI research and analysis.
Related and recommended next reads
 PerMIT: Protecting Persistent Memory for LLM Agents with Content Confirmation and Community Trust
Recommended next · October 23, 2026
 PACT: Testing Enterprise AI Agent Compliance Under Pressure
Recommended next · October 11, 2026
 Hypothesis-Driven Autonomous Materials Synthesis with Multimodal LLM Agents
Recommended next · October 10, 2026