Sphere Encoder 2: Image Generation with Rotation in a Spherical Latent Space
This paper introduces Sphere Encoder 2, a single-stage autoencoder for image generation that improves ImageNet samples by covering the equatorial region of its spherical latent space and separating reconstruction from generation.
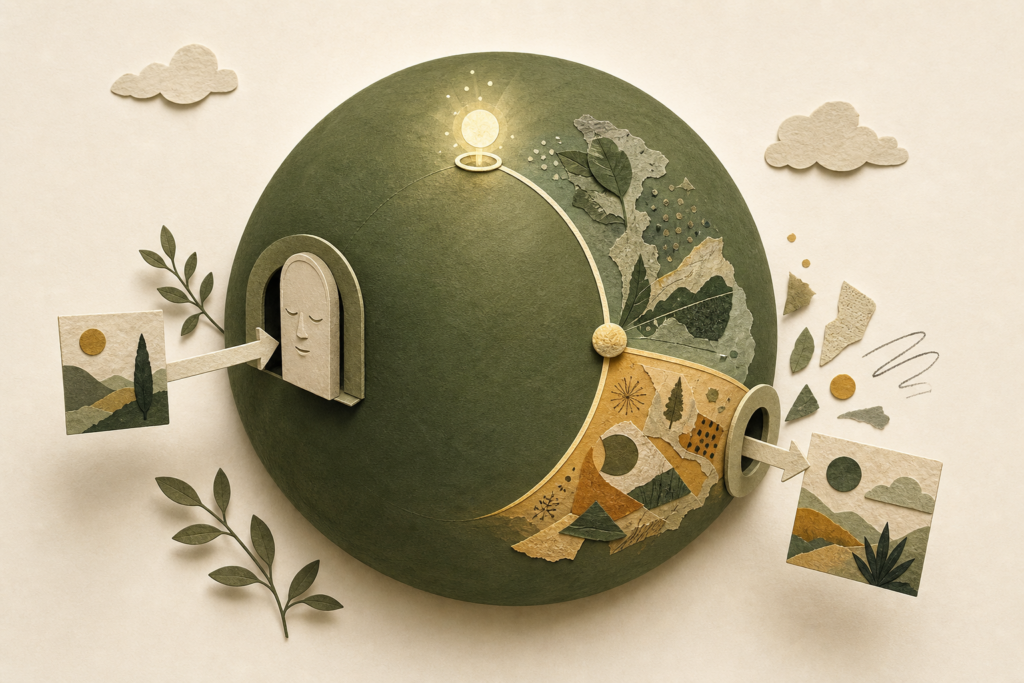
Table of contents
This overview is based on the available arXiv preprint, arXiv:2610.02208v1 dated October 1, 2026, and this section does not independently confirm its peer-review status. Sphere Encoder 2 is a non-variational autoencoder for image generation: an encoder maps an image to a vector on a high-dimensional sphere, and a decoder maps that vector back to an image. The central goal is to decode a random spherical point directly into pixels, even in one step, rather than relying on a many-step process such as diffusion.
The paper identifies two issues in the original Sphere Encoder. First, training noise reached only 85 degrees, while random points on a high-dimensional sphere concentrate near the equator; this leaves a five-degree gap before the region used in one-step generation. Sphere Encoder 2 replaces additive noise plus reprojection with an explicit rotation, combining cos(α)z and sin(α)F(e). Thus, α is defined from zero to 90 degrees, and the 90-degree endpoint is exactly the random direction used for generation.
The second issue is applying pixel-wise reconstruction loss along the whole rotation path, which can favor averages of plausible images and produce blur. The new method splits the path at a default cutoff of 70 degrees. At low angles, it retains a combination of LPIPS and L1 reconstruction losses. At higher angles, it removes pixel loss and uses semantic alignment of ConvNeXt logits, latent consistency, and a score-matching loss. A sigmoid with default bandwidth of five degrees weights the transition between the two regimes.
For score matching, features of real and generated images are extracted by a frozen ConvNeXt V2-N network. Two small two-layer score models are then trained online, one on real features and one on generated features. The difference between their outputs provides an update direction for the decoder so generated features move toward the real distribution; the score models themselves are frozen during this transport. The authors present this as an alternative that does not require adversarial training or a pretrained diffusion teacher, not as evidence of universal superiority across settings.
In the reported configuration, DINOv3-small is a frozen encoder, while only a Base or Large ViT decoder is trained. On ImageNet, Sphere2-L without CFG and with four network evaluations reports FDr6 of 5.77 at 256×256 and 6.35 at 512×512; the FD-lite variant reports 5.14 and 6.60, respectively. Sphere2-B reports FDr6 of 14.53 with one step at 256×256. For Sphere2-L at 512×512 and batch size 16, the paper also reports two minutes to generate 50,000 images in one unguided step and 14 minutes in four CFG steps. These are results from the paper’s own experiments and metrics.
The limitations matter. Quality is reported as stronger under FDr6 than under gFID, and the authors attribute this gap to the ConvNeXt feature space used by the score loss and a statistical shift in the older Inception space. FD-lite reduces this issue in many cases, but worsens one-step FDr6 for Sphere2-L. Evaluations use class-conditional Oxford Flowers and ImageNet; the paper does not test text-to-image generation, other datasets, or human preference. Low-angle reconstructions also intentionally omit adversarial sharpening and may retain soft or "waffle-like" textures.
Explore more research
Read more AI research and analysis.