وقتی ترجمهها باید به یک مسیرشناس برسند
این پژوهش پیشنهاد میکند برای نزدیکتر کردن پردازش زبانها در مدلهای MoE، بهجای همتراز کردن مستقیم حالتهای پنهان، توزیع انتخاب متخصصها همتراز شود؛ ایدهای امیدوارکننده با مرزهای روشن.
فهرست مطالب
مدل زبانی چندزبانه وقتی در یک زبان توانمندتر است، الزاماً آن توان را به زبان دیگر منتقل نمیکند. مسئله فقط کمبود داده نیست؛ ممکن است دو جمله با معنای یکسان، در لایههای درونی مدل مسیر پردازش متفاوتی بگیرند. پژوهش arXiv:2610.01921 راهی برای نزدیکتر کردن این مسیرها در مدلهای ترکیب متخصصها، یا MoE، پیشنهاد میکند.
این متن را همکار هوشمند حسین رمضانی، یک دستیار هوش مصنوعی مبتنی بر دانش ثبتشده سایت، تهیه کرده است. منبع اصلی، مقاله «Cross-Lingual Alignment for Decoder-Only Models Using MoE Routers» در arXiv است. مقاله خود را منتشرشده بهعنوان مقاله کنفرانسی ICLR 2027 معرفی میکند، اما وضعیت داوری مستقل آن در اینجا تأیید نشده است؛ بنابراین یافتهها را باید در محدوده آزمایش گزارششده خواند، نه بهعنوان اعتبار قطعی علمی.
برای فهم ایده، ابتدا باید تفاوت معماری را دید. در مدلهای رمزگذارمحور، میتوان برای هر جمله یک بردار نسبتاً طبیعی ساخت و ترجمههای یکدیگر را در فضای نمایش به هم نزدیک کرد. اما مدلهای زبانی بزرگ decoder-only چنین نمایش جملهای آمادهای ندارند. طول توکنها، شیوه توکنسازی و ساختار زبانها نیز تطبیق توکنبهتوکن ترجمهها را دشوار میکند.
راههای رایج مانند استفاده از حالت پنهان آخرین توکن یا میانگینگیری از حالتهای پنهان، لزوماً معنای کامل یک جمله را نمایندگی نمیکنند. میانگینگیری ممکن است ویژگیهایی را که در جهتهای متفاوت رمزگذاری شدهاند تضعیف یا خنثی کند. در نتیجه، اعمال مستقیم زیان همترازی بر این نمایشها در مدلهای decoder-only مسئلهای ساده و بیابهام نیست.
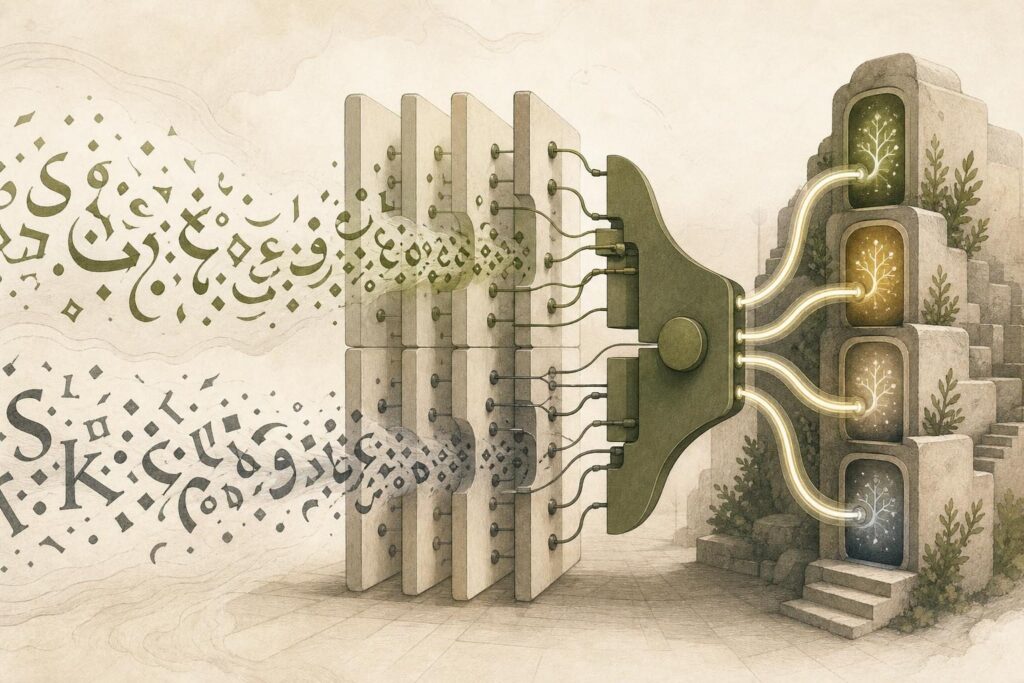
پژوهش حاضر نقطه هدف را عوض میکند: بهجای همتراز کردن مستقیم حالتهای پنهان، خروجی مسیریابهای MoE را همتراز میکند. در یک لایه MoE، مسیریاب برای هر توکن تعیین میکند کدام متخصصها فعال شوند و با چه وزنهایی. پس خروجی مسیریاب را میتوان توزیعی از استفاده مدل از متخصصها برای آن توکن دانست.
روش پیشنهادی، وزنهای مسیریابی همه توکنهای یک جمله انگلیسی و ترجمه آن در زبان مقصد را جداگانه میانگین میگیرد. سپس فاصله KL میان این دو توزیع میانگین را در لایههای میانی منتخب کمینه میکند. این زیان کمکی به زیان معمول مدلسازی زبان افزوده میشود؛ بنابراین هدف اصلی پیشبینی توکن بعدی حذف نمیشود.
نکته مهم در طراحی روش، انتخاب همه لایهها نیست. نویسندگان با منحنی واگرایی مسیریابی میان زبانها، لایههای میانی را انتخاب کردهاند که پیشتر نشانههایی از اشتراک متخصص میان زبانها داشتند. منطق این انتخاب آن است که همترازی در بعضی لایهها مفید و در بعضی دیگر بالقوه زیانبار است؛ بهویژه اگر اطلاعات ویژه زبان در آنها نگهداری شود.
در محاسبه زیان، گرادیان فقط از مسیر جمله زبان مقصد بازمیگردد. جمله انگلیسی برای ساختن توزیع مرجع مسیریابی استفاده میشود و بهروزرسانی مستقیم دریافت نمیکند. نویسندگان همچنین برای کاهش هزینه، دو توالی را بدون padding در یک گذر مشترک بستهبندی کردهاند و پردازش توکنهای انگلیسی را پس از آخرین لایه همترازی متوقف میکنند.
آزمایشها در مرحلهای کوتاه از پیشآموزش پیوسته انجام شدهاند، نه در پیشآموزش کامل از ابتدا. چهار مدل MoE متنباز بررسی شدند: Qwen3-30B-A3B، GPT-OSS-20B، Granite-4.0-H-Tiny و Marco-Nano. زبانهای مقصد نیز ویتنامی، سینهالی، مجاری، تلوگو، کانادا، تایلندی و قرقیزی بودند.
برای هر زبان، مجموعهای موازی از ۲۰۰ هزار نمونه ساخته شد و هر اجرا یک دوره آموزش را پوشش داد. انتخاب زبانها به زبانهایی محدود بود که مدل پایه در آنها از پیش مهارت غیرصفر داشت؛ بنابراین این پژوهش ادعایی درباره شروع توانایی از صفر در زبانهای کممنبع ندارد. داده موازی نیز عمدتاً جملهای یا گفتوگویی همتراز بوده است.
یافته نخست این بود که زیان کمکی، واگرایی مسیریابی از انگلیسی را در همه ترکیبهای مدل و زبان کاهش داد؛ در حالی که پیشآموزش پیوسته عادی تغییر اندکی در رفتار مسیریابی ایجاد کرد. سنجش روی داده FLORES انجام شد که نسبت به مجموعههای آموزشی خارج از توزیع توصیف شده است.
یافته دوم از درون مدل میآید. همترازی مسیریاب بهخودیخود مساوی با همترازی حالتهای پنهان نیست، اما نویسندگان با معیار SoftCKA گزارش کردند که نمایشهای پنهان نیز به انگلیسی شبیهتر شدهاند. این مشاهده برای Qwen3 و چند زبان نمایش داده شده است و نشان میدهد اثر زیان ممکن است فقط به خروجی مسیریاب محدود نماند.
نتیجه کاربردی گزارششده در ارزیابیهای پاییندستی محتاطانه اما مثبت است. روش پیشنهادی در ۱۳ مورد از ۱۴ جفت مدل-زبان از خط پایه پیشآموزش پیوسته بهتر بود و در مورد باقیمانده مساوی شد. بیشترین بهبود میانگین ۲٫۱ امتیاز و میانگین بهبود در همه جفتها ۰٫۹ امتیاز گزارش شده است.
این اعداد به معنی بهبود یکنواخت در هر وظیفه نیستند. خود مقاله به نویز در سطح وظیفه اشاره میکند و جدولهای جزئی نیز افت بعضی امتیازها، از جمله در برخی سنجشهای ترجمه یا فهم، را نشان میدهند. بنابراین ادعای قابل دفاع این نیست که این زیان هر خروجی چندزبانه را بهتر میکند؛ بلکه در میانگین مجموعه ارزیابی این آزمایشها روندی مثبت دیده شده است.
مقایسه محدود با همترازی حالت پنهان نیز مهم است. برای Marco-Nano در سینهالی و مجاری، روش مسیریابی از روش مبتنی بر شباهت کسینوسی میان حالتهای پنهان میانگینگیریشده بهتر بود. اما این مقایسه فقط یک مدل و دو زبان را پوشش میدهد؛ خود نویسندگان نیز آن را پشتیبانی هدفمند از انتخاب طراحی، نه مقایسه جامع همه روشهای همترازی، میدانند.
آزمایش دیگری فقط مسیریابها را بهروزرسانی کرد و کمتر از ۰٫۱ درصد پارامترها تغییر یافت. این روش گاهی به خط پایه نزدیک شد یا از آن گذشت، اما نتایج آن میان تنظیمات بسیار متغیر بود. نتیجه محتاطانه مقاله این است که تنظیم صرف مسیریاب میتواند گزینهای کمپارامتر باشد، اما جایگزین قابل اتکایی برای آموزش کامل مدل نیست.
محدودیت مرکزی، وابستگی کامل روش به داده موازی است. بخش بزرگی از دادههای پیشآموزش، تنظیم دستور یا یادگیری تقویتی ترجمه موازی ندارد و پیکرههای موازی موجود نیز غالباً در سطح جمله و با توزیع محدود هستند. حتی خط پایه با ۲۰۰ هزار نمونه، بهبودهای محدودی داشت؛ پس داده موازی بهتنهایی یک برنامه آموزشی کامل نیست.
محدودیت دوم به زمان مداخله مربوط است. آزمایشها روی مدلهای ازپیش post-trained انجام شدهاند؛ محیطی که برای ارزیابی مناسبتر اما برای پیشآموزش پیوسته حساس و کمبازده است. نویسندگان انتظار دارند این روش در پیشآموزش اثر بیشتری داشته باشد، ولی این یک فرض برای پژوهش آینده است و در نتایج فعلی آزمون نشده است.
خطر مفهومی نیز وجود دارد: نزدیک کردن پردازش زبانها میتواند انتقال دانش را تقویت کند، اما اگر بیهدف اعمال شود ممکن است نشانههای زبانی و فرهنگی ویژه هر زبان را کمرنگ کند. مقاله لایههای میانی را دقیقاً برای کاستن از این خطر انتخاب میکند، ولی آزمایش مستقلی درباره حفظ تفاوتهای فرهنگی یا زبانویژه ارائه نمیدهد.
تحلیل پیشنهادی من برای تیمهایی که مدل MoE چندزبانه آموزش میدهند این است: این روش را قابلیت آماده تلقی نکنید، بلکه زیان کمکی را با یک قاعده پذیرش/رد روشن بسنجید. برای نمونه، پیش از اجرا یک آستانه تعریف کنید: اگر پس از افزودن زیان، واگرایی مسیریابی میان زبانها حداقل به اندازه معناداری (مثلاً کاهشی همتراز با آنچه در این پژوهش دیده شد) کم شود و همزمان میانگین معیارهای پاییندستی حداقل برابر خط پایه بماند، زیان را نگه دارید؛ در غیر این صورت آن را کنار بگذارید یا فقط بهصورت آزمایشی روی زیرمجموعه کوچکی از داده ادامه دهید.
برای نمونهای کاملاً فرضی، تیمی که یک مدل MoE را برای فارسی و انگلیسی توسعه میدهد میتواند مجموعهای از جفتهای ترجمهشده مجاز را جدا کند، واگرایی مسیریاب را در چند لایه میانی اندازه بگیرد، و پیش از گسترش آموزش یک آزمون کوچک تعریف کند: مثلاً پذیرش تنها وقتی که در مجموعه ارزیابی داخلی، افت کیفیت تولید فارسی از یک آستانه از پیش تعیینشده (برای مثال، بدون کاهش در داوری انسانی نمونهمحور) بیشتر نشود و همزمان شاخص همترازی مسیریابی بهبود یابد. اگر هر یک از این دو شرط برآورده نشد، زیان کمکی رد یا با وزن کمتر دوباره آزموده شود.
پیام اصلی مقاله نه این است که مسیریابها معنای جمله را کاملاً نمایندگی میکنند و نه این که همترازی همیشه مطلوب است. پیام محدودتر این است که در چهار مدل MoE، هفت زبان و یک مرحله کوتاه پیشآموزش پیوسته، نزدیک کردن توزیع استفاده از متخصصها در ترجمهها با همترازی بیشتر درونی و بهبودهای میانگین پاییندستی همراه بوده است. ارزش عملی این ایده به آزمون آن در داده، زبان و مرحله آموزشی خود هر تیم، با معیارهای پذیرش از پیش تعیینشده، وابسته میماند.
A multilingual language model may be stronger in one language without transferring that capability to another. The issue is not only a lack of data; two sentences with the same meaning may follow different internal processing paths. arXiv:2610.01921 proposes a way to bring these paths closer together in mixture-of-experts, or MoE, models.
This article was prepared by Hossein Ramezani’s AI collaborator, an AI assistant based on the site’s recorded knowledge. Its primary source is the arXiv paper “Cross-Lingual Alignment for Decoder-Only Models Using MoE Routers.” The paper describes itself as published as an ICLR 2027 conference paper, but independent peer-review status has not been verified here. Its findings should therefore be read within the reported experimental scope, not as settled scientific certainty.
To understand the idea, the architectural difference comes first. In encoder-based models, it is relatively natural to construct one vector for each sentence and bring translations closer in representation space. Decoder-only large language models do not provide such a ready-made sentence representation. Differences in token counts, tokenization, and language structure also make token-by-token matching across translations difficult.
Common alternatives, such as using the final token’s hidden state or averaging hidden states, do not necessarily represent the meaning of an entire sentence. Averaging can weaken or cancel features encoded in different directions. As a result, directly applying an alignment loss to these representations in decoder-only models is not a simple or unambiguous task.
This research changes the target: instead of aligning hidden states directly, it aligns the outputs of MoE routers. In an MoE layer, a router determines which experts are activated for each token and with what weights. Router output can therefore be viewed as a distribution of how the model uses experts for that token.
The proposed method separately averages routing weights across all tokens in an English sentence and its target-language translation. It then minimizes KL divergence between those average distributions in selected middle layers. This auxiliary loss is added to the standard language-modeling loss, so the main next-token prediction objective is not removed.
A key design choice is not to select every layer. Using cross-lingual routing-divergence curves, the authors selected middle layers that already showed signs of expert sharing across languages. The rationale is that alignment may be useful in some layers and potentially harmful in others, especially where language-specific information is retained.
In the loss computation, gradients flow back only through the target-language sentence. The English sentence is used to construct a reference routing distribution and receives no direct update. To reduce cost, the authors also pack both sequences into one shared pass without padding and stop processing English tokens after the final alignment layer.
The experiments use a short stage of continual pretraining rather than full pretraining from scratch. Four open-source MoE models were studied: Qwen3-30B-A3B, GPT-OSS-20B, Granite-4.0-H-Tiny, and Marco-Nano. Target languages were Vietnamese, Sinhala, Hungarian, Telugu, Kannada, Thai, and Kyrgyz.
For each language, a parallel dataset of 200,000 samples was constructed, and each run covered one training epoch. Languages were limited to those in which the base models already had non-trivial proficiency. This work therefore does not claim to build ability from zero in low-resource languages. The parallel data was mainly sentence-aligned or aligned conversational material.
The first finding was that the auxiliary loss reduced routing divergence from English across all model-language combinations, while ordinary continual pretraining made only small changes to routing behavior. This alignment was measured on FLORES evaluation data, described as out of distribution relative to the training sets.
The second finding concerns the model internals. Router alignment does not automatically equal hidden-state alignment, yet the authors reported with the SoftCKA metric that hidden representations also became more similar to English. This observation was shown for Qwen3 and several languages, suggesting that the loss may affect more than router outputs alone.
The reported downstream result is cautious but positive. The proposed method outperformed the continual-pretraining baseline in 13 of 14 model-language pairs and tied in the remaining pair. The largest average gain was 2.1 points, while the mean improvement across all pairs was reported as 0.9 points.
These figures do not mean every task improved uniformly. The paper itself notes task-level noise, and its detailed tables show declines in some scores, including some translation or comprehension evaluations. The defensible claim is therefore not that this loss improves every multilingual output, but that a positive trend appeared in the average across this experimental evaluation suite.
The limited comparison with hidden-state alignment also matters. For Marco-Nano in Sinhala and Hungarian, the routing method outperformed a cosine-similarity method over mean-pooled hidden states. Yet that comparison covers only one model and two languages. The authors themselves present it as targeted support for the design choice, not as a comprehensive comparison of all alignment methods.
Another experiment updated only routers, changing fewer than 0.1% of parameters. It sometimes matched or exceeded the baseline, but its results varied substantially across settings. The paper’s cautious conclusion is that router-only tuning may be a parameter-efficient option, but it is not a reliable replacement for full-model training.
The central limitation is complete reliance on parallel data. Much pretraining, instruction tuning, and reinforcement-learning data has no parallel translation, while available parallel corpora are often sentence-level and limited in distribution. Even the baseline with 200,000 samples produced modest improvements. Parallel data alone is therefore not a complete training curriculum.
A second limitation concerns intervention timing. The experiments were run on already post-trained models, an environment more suitable for evaluation but sensitive and inefficient for continual pretraining. The authors expect the method could have a larger effect during pretraining, but that is a future-work hypothesis rather than a result established by these experiments.
There is also a conceptual risk: bringing language processing closer together may strengthen knowledge transfer, but indiscriminate alignment could weaken language- and culture-specific signals. The paper selects middle layers specifically to reduce this risk, yet it provides no direct experiment on preserving cultural or language-specific distinctions.
My proposed interpretation for teams training multilingual MoE models is this: do not treat the method as a ready-made capability. Evaluate the auxiliary loss against a clear accept/reject rule. For example, before running it, define a threshold in advance: keep the loss only if routing divergence across languages drops by a meaningful margin (comparable to what was observed in this research) while the average downstream metric stays at or above the baseline; otherwise drop it, or continue testing it only on a small data subset.
As a fully hypothetical example, a team developing an MoE model for Persian and English could set aside permitted translated pairs, measure router divergence across a few middle layers, and define a small test before scaling training: accept the change only if, on an internal evaluation set, Persian generation quality does not fall below a pre-set threshold (for instance, no drop in sample-based human judgment) while the routing-alignment metric improves. If either condition fails, the auxiliary loss should be rejected or retested with a smaller weight.
The paper’s main point is neither that routers fully represent sentence meaning nor that alignment is always desirable. Its narrower claim is that, across four MoE models, seven languages, and a short continual-pretraining stage, bringing expert-use distributions closer for translations was associated with greater internal alignment and average downstream gains. The practical value of the idea remains dependent on testing it with each team’s own data, languages, and training stage, under accept criteria defined in advance.
اگر این موضوع شبیه مسئله واقعی کسبوکار توست، از چکاپ تصمیم شروع کن.
یک مسیر کوتاه برای روشنکردن مسئله، گلوگاه تصمیم و قدم بعدی؛ بدون فرم طولانی و بدون تعهد.