PerMIT: Protecting Persistent Memory for LLM Agents with Content Confirmation and Community Trust
PerMIT is a memory architecture for LLM agents that keeps unconfirmed environment-derived content behind a confirmation gate, machine-checks a specified single-user core in Lean 4, and proposes logged-confirmation-based trust for shared memory.
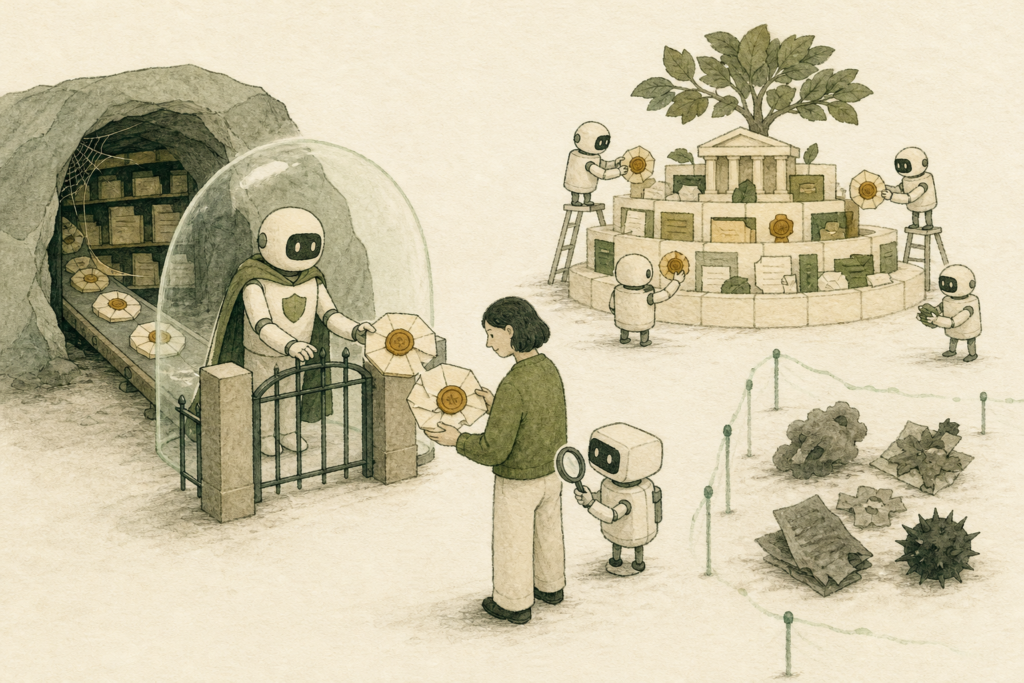
Table of contents
This introduction is based on the arXiv preprint version arXiv:2610.28987v1, dated October 20, 2026; its independent peer-review status is not confirmed in the text. The paper studies persistent memory in large-language-model agents: web content, tools, files, or code can contain injected instructions, remain in memory, and affect a sensitive agent action in a later session. PerMIT limits this route by placing the trust boundary at the memory interface rather than in the agent’s reasoning.
In the single-user tier, the protected agent, or P-LLM, accesses memory only through an interface with seven operations: write, recall, fill, crystallize, display, confirm, and evict. Environment-derived content and quarantined-reader summaries remain untrusted and are presented to the P-LLM as opaque handles rather than readable text. The reader can search untrusted memory but has no tool-calling capability. A value becomes usable after its value, source, user instruction, and target tool are displayed at the confirmation gate.
The paper formalizes two properties. Action Integrity states that an argument to a sensitive tool must be user-typed content or a value that the same user confirmed with the same bytes for that same tool. Reasoning Integrity modulo the display transcript states that, with identical typed inputs, coupled randomness, schedules, and complete display transcripts, differences in untrusted memory must not change P-LLM behavior. The single-user core is machine-checked in Lean 4, but the federated tier and probabilistic analysis are outside that scope.
In the federated tier, each accepted confirmation for an exact value and tool becomes a signed, logged endorsement for that entry. After reaching a threshold of N fresh endorsements from distinct identities, an entry becomes community-confirmed, and later users do not need repeated confirmation along the specified path. A qualifying rejection does not immediately delete the entry; it freezes promotion and sends the dispute to a demand-paced panel. The bound on poisoned-content promotion depends on reviewer accuracy, adversarial capacity, and threshold and panel settings; this trust does not mean factual correctness.
On Trojan Hippo, PerMIT configurations with self-verification and two lightweight Qwen verifiers recorded zero observed attack success across the four main models; this does not establish zero risk. A federated simulation with five billion promotion attempts, a 120-user community, and 122 entries reduced required approvals by 2.36 per user on average, or 38%. On τ²-bench, with up to 90 autonomous agents, none of 12 direct-injection payloads became community-confirmed, and constructed knowledge produced reported significant improvements on held-out telecom tasks for Sonnet and Kimi; GLM-5’s effect interval included zero.
The limitations are fundamental. The guarantees depend on source labeling, immutable blocks, faithful display, and sound confirmation decisions; the accuracy of an LLM verifier is not proved. Confirmation is tied to a value and tool, not to purpose, time, argument position, or an entire transaction, so separately endorsed values may be combined inappropriately. The paper leaves timing channels, compromised agents or enforcement harnesses, poison unrecognizable to reviewers, and adaptive payload search against live verifiers outside complete coverage. In the banking experiment, it also reported no detectable improvement over the no-knowledge condition.
Explore more research
Read more AI research and analysis.
Related and recommended next reads
 PACT: Testing Enterprise AI Agent Compliance Under Pressure
Recommended next · October 11, 2026
 Hypothesis-Driven Autonomous Materials Synthesis with Multimodal LLM Agents
Recommended next · October 10, 2026
 LiteReality-Agent: Agentic Reconstruction of Interactive 3D Indoor Scenes
Recommended next · October 8, 2026