Cross-Lingual Alignment in MoE Models Through Router Outputs
This paper introduces a method for aligning processing across languages in decoder-only MoE models by bringing the mean expert-routing distributions of translated sequences closer together. Experiments on four models and seven languages report gains of up to 2.1 average points over a continual-pretraining baseline; independent peer review of this version is unconfirmed.
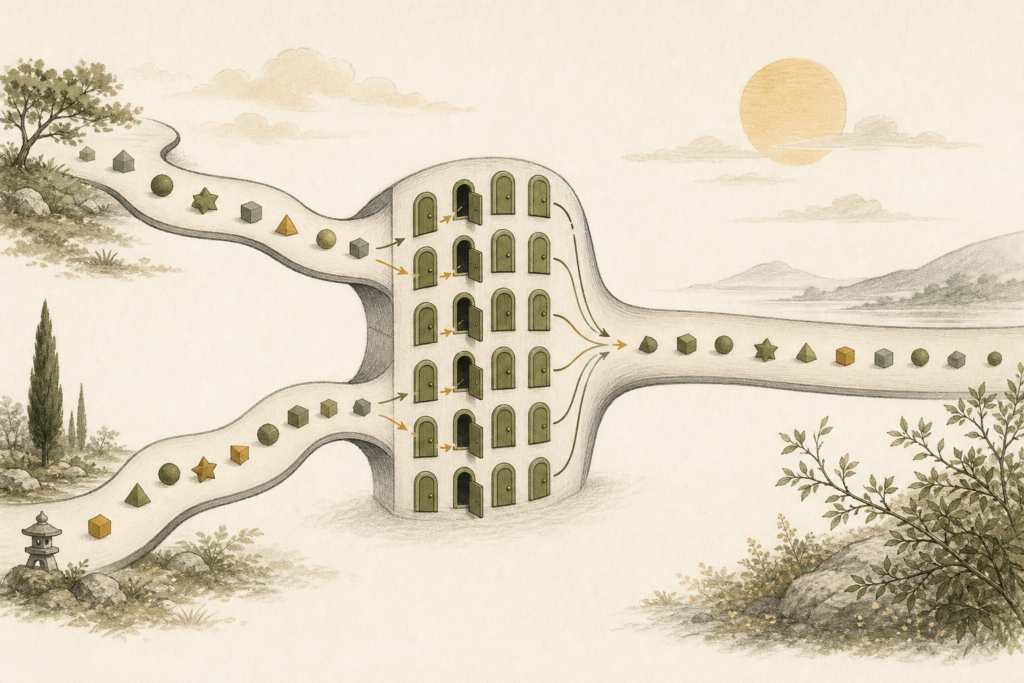
Table of contents
This introduction relies on the preprint version available on arXiv, arXiv:2610.01921v1 dated October 1, 2026. The paper text makes no mention of peer review or formal acceptance, and its independent peer-review status is unconfirmed here. The paper studies cross-lingual representation alignment in decoder-only large language models. In these models, differences in tokenization and the absence of a natural sequence-level representation make direct comparison of translated sentences difficult. The authors propose aligning router outputs in mixture-of-experts (MoE) architectures rather than directly aligning hidden states.
In an MoE, a router produces a distribution over experts for each token, while only a subset is activated. The proposed method first averages routing weights across all tokens in an English sequence and its translation. It then computes KL divergence between these distributions in selected middle layers and adds it to the language-modeling loss. Gradients pass only through the target-language sequence; the English sequence is used solely as a routing-distribution reference. Layers are selected using cross-language routing-divergence curves.
The experiments run a short continual-pretraining stage, consisting of one pass over 200,000 parallel English–target-language samples for each language; 1,000 examples are reserved for validation. They examine Qwen3-30B-A3B, GPT-OSS-20B, Granite-4.0-H-Tiny, and Marco-Nano. Target languages are Vietnamese, Sinhala, Hungarian, Telugu, Kannada, Thai, and Kyrgyz. Data are constructed from sentence-aligned text and parallel instruction–response conversations, and evaluation is limited to languages where the base model already has non-trivial capability.
To reduce cost, the authors pack source and target sequences into a shared pass without padding; English tokens exit computation after the final alignment layer. On FLORES data that are out of distribution relative to training, the auxiliary loss produced the largest routing-divergence reduction relative to the base model or standard CPT for all models and languages. SoftCKA, reported for Qwen3, also shows increased hidden-state similarity to English after training; the reported effect is therefore not limited to router outputs.
Downstream evaluation covers generation, understanding, knowledge, physical reasoning, and mathematical reasoning, including FLORES, Belebele, Global-MMLU, MMLU-ProX, MultiLoKo, INCLUDE, Global-PIQA, MGSM, and PolyMath. Average scores over available tasks improved over baseline CPT in 13 of 14 model–language pairs and tied in one case, Marco-Nano for Vietnamese. The largest average gain was 2.1 points, while the mean gain across all pairs was 0.9 points. In the limited Marco-Nano comparison, routing loss obtained 26.8 versus 26.3 for hidden-state alignment in Sinhala, and 38.1 versus 36.9 in Hungarian.
The limitations are important. Experiments are short and use post-trained models; CPT is sensitive in this setting, and the baseline itself generally gains only modestly. The method depends entirely on parallel data, whereas much training data are not parallel and available corpora are mainly sentence-level. The authors did not test negative pairs or the interaction between the proposed loss and MoE load balancing. The hidden-state alignment comparison covers only two languages and one model, and results do not establish which task types benefit more. Pretraining-scale effects were not tested.
Explore more research
Read more AI research and analysis.