Mingbird: A Local-First Harness for Small-Model Agents
This preprint examines whether improving an agent harness, without changing the model, can make small open models more reliable on real tasks in Windows.
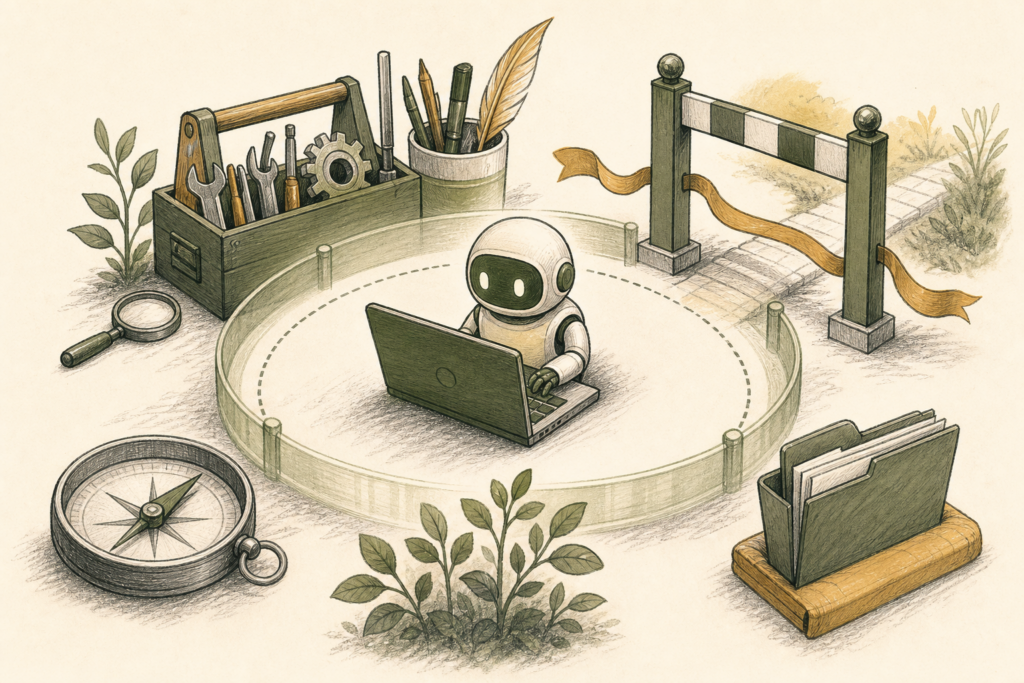
Table of contents
This summary relies on preprint arXiv:2610.02001v1, published October 1, 2026. The paper provides no indication of peer review or acceptance at a journal or conference; its independent peer-review status is therefore unconfirmed and it should not be treated as a peer-reviewed result. The authors introduce Mingbird as a local-first agent harness for Windows and Ollama, emphasizing that the contribution is systems engineering rather than a new algorithm or inference method.
The central claim is that a substantial share of small open models’ (2–9B parameters) failures on multi-step tasks may arise from the surrounding harness rather than solely from model capability. According to the authors, harnesses designed for large cloud models can crowd context with tool schemas, create tool-demonstration loops, discard malformed calls, or wrongly accept incomplete work as complete. Testing extends up to the 35B tier.
Mingbird includes ten core mechanisms and a five-ring safety model. Three highlighted components are a flat, category-routed prefill with a byte-level net-zero growth budget; a finish gate that reinserts the original task text before accepting a completion claim and checks delivery; and loop detection using signatures built from tool names and normalized arguments. Automatic file backups, recovery from empty outputs and Windows encoding errors, and path-security boundaries are also part of the design.
The internal LRAB evaluation is a self-built controlled comparison: 4 harnesses, 4 open models at nominal 2B, 4B, 12B, and 35B tiers, and 18 real tasks, for 288 experimental cells. All runs used one Windows computer with an integrated GPU and 32 GB shared memory, Ollama, equal time budgets, and deterministic artifact-based scoring. Mingbird averaged 0.886, versus 0.631 for goose, 0.479 for opencode, and 0.405 for agent-mini; raw results for all cells are published.
At 2B, Mingbird scored 0.821, while the three competitors ranged from 0.017 to 0.271; the pattern also appeared in a second small-tier model family, qwen3.5:2b, at 0.779 versus 0.017–0.239. Paired Wilcoxon tests with Holm correction report significant advantages at the 2B and 12B tiers. On τ²-bench, a third-party benchmark with 278 tasks across three domains, scores were 0.856 for Mingbird, 0.791 for the benchmark’s native agent, and 0.737 for opencode; the goose arm was not completed due to low throughput.
Mechanism-level evidence is not conclusive. Removing the finish gate in the 2B, 18-task test reduced the mean from 0.821 to 0.723, but every bootstrap confidence interval crossed zero and same-night reruns varied by up to 0.069. The only batch-matched comparison, full mechanisms versus text re-reading alone, showed roughly a 0.10 advantage for executable guards across three replications. Important limitations include the self-built benchmark, development-evaluation overlap for some mechanisms, a single test machine, non-randomized campaign ordering, and mostly single-trial results; the findings have not yet been independently replicated or peer reviewed.
Explore more research
Read more AI research and analysis.
Related and recommended next reads
 PerMIT: Protecting Persistent Memory for LLM Agents with Content Confirmation and Community Trust
Recommended next · October 23, 2026
 Enterprise AI Assistant Compliance Under Pressure
Recommended next · October 13, 2026
 PACT: Testing Enterprise AI Agent Compliance Under Pressure
Recommended next · October 11, 2026